参数良率:半导体里被误解最深的概念 —— Irrational Analysis 长文精读(附 Cerebras 案例)
参数良率决定了同一颗硅片能卖几个价钱、能跑多快。这篇来自一位做过后硅验证的从业者,用 AMD 与 NVIDIA 的分档 SKU、工艺角与 DVFS 讲清机制,并据此判断 Cerebras 的晶圆级路线为何是最极端的受害者。含 46 张配图与英文原文全文。
来源:Irrational Analysis(Substack 半导体投资专栏,作者曾从事后硅验证工作,专栏为匿名署名),2026 年 10 月 4 日发布,全文公开、未设付费墙。 原文:Practical Parametric Yield — https://irrationalanalysis.substack.com/p/practical-parametric-yield 体量:约 4,450 词,含 46 张配图与 2 张动图。 转载说明:第一部分为英文原文完整转载,含全部 46 张配图(图注为本站所加中文说明;原文自带的 3 处作者图注已并入对应图注)。原文语气强烈、含粗口,并包含指向具体公司与个人、无法独立验证的归因,本站未作任何删改以保持原貌;请读者自行区分可验证的工程事实与不可验证的行业叙事。版权归原作者所有。第二部分为本站独立撰写的中文结构化解读,其中的质疑与推算属解读者观点,不构成投资建议。
第一部分:英文原文(Original Article)
Irrational Analysis is heavily invested in the semiconductor industry.
- Positions will change over time and are regularly updated.
Opinions are authors own and do not represent past, present, and/or future employers.
All content published on this newsletter is based on public information and independent research conducted since 2011.
This newsletter is not financial advice and readers should always do their own research before investing in any security.
Feel free to contact me via email at: irrational_analysis@proton.me
Parametric yield is possibly the worst understood concept within semiconductors. It’s frankly surprising how many people work in this industry and are either clueless or have a very wrong view on how parametric yield works.
Clock speed, power draw, and final product-level yield are an economic choice, not a design choice.
Important background information is available here and highly recommended as a pre-requisite if you want to understand the technical matters properly.
图 1|作者前作(PDK 技术长文)的目录页,文首建议先读这篇再读本文。
For this post, I will attempt to abstract out the technical details and keep things practical and intuitive. Will heavily rely on public examples and obfuscated first-hand experience. Sections 6.d, 6.e, and 6.f of the old PDK technical deep-dive are of particular interest.
(please please read the old post it will help you understand this one so much)
This parametric yield deep-dive has been sitting in drafts for over a year. Given that Cerebras is such a hot topic, I bumped this one to the top and re-wrote large portions around their chip.
Parametric yield is an industry-wide issue. Cerebras is disproportionately effected by this problem.
**Understanding why Cerebras is disproportionately harmed by parametric yield and how they could mitigate this problem is key to understanding the stock.
I would argue it is the only thing that matters for the next 12-18 months for them.**
Before jumping into the content, I want to finish this intro with a fun story.
Two years ago, I managed to weasel my way into the private launch briefing for WSE3 with the help of a friend. It took place on March 12th, 2024 at Colovore, a local Bay-Area colocation hosting provider Cerebras used for some of their capacity at the time.
I have been a huge fan of Cerebras since 2019. To be able to see the new WSE3 in real life was so exciting. Took a day off from dayjob to attend. Here are some of the pictures I took.
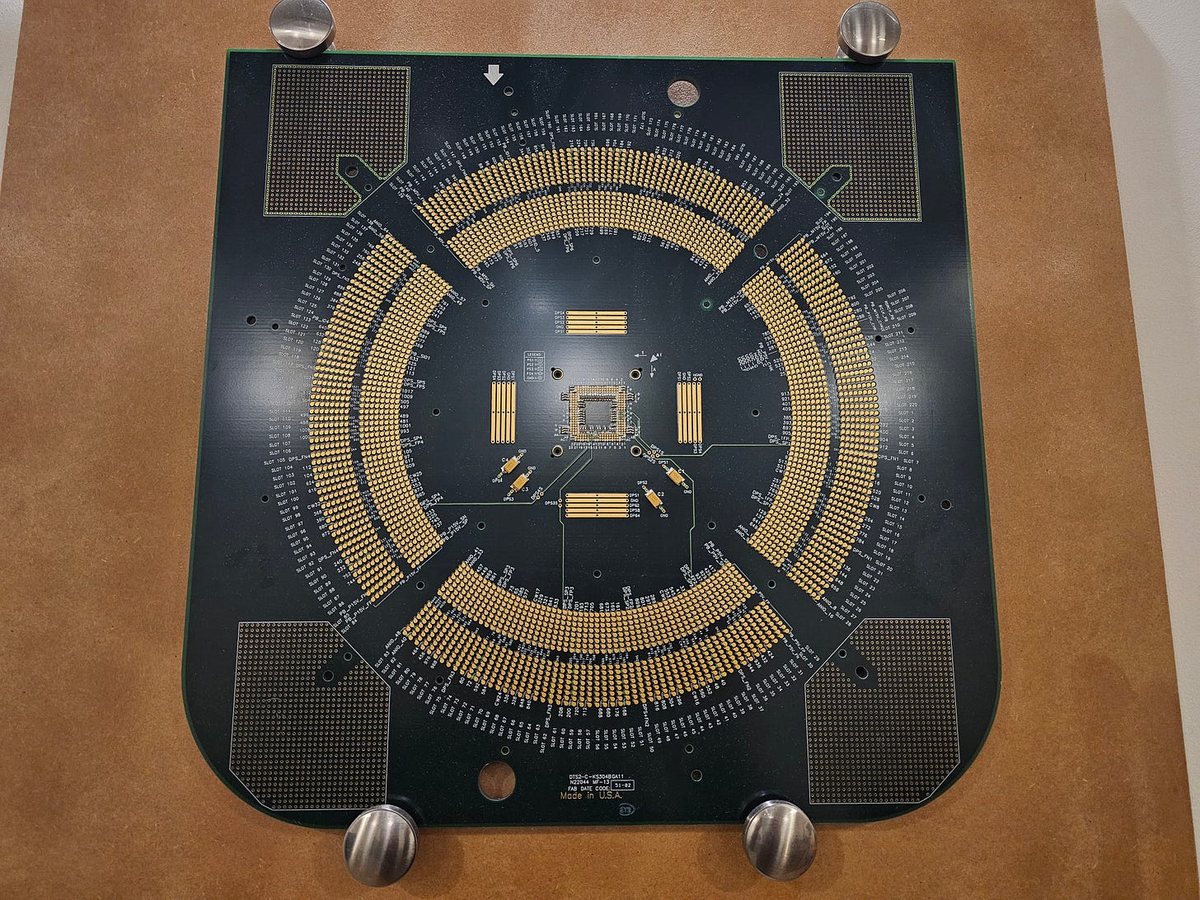
图 2|WSE-3 晶圆实物——2024 年 3 月 12 日 Colovore 私人发布会现场。
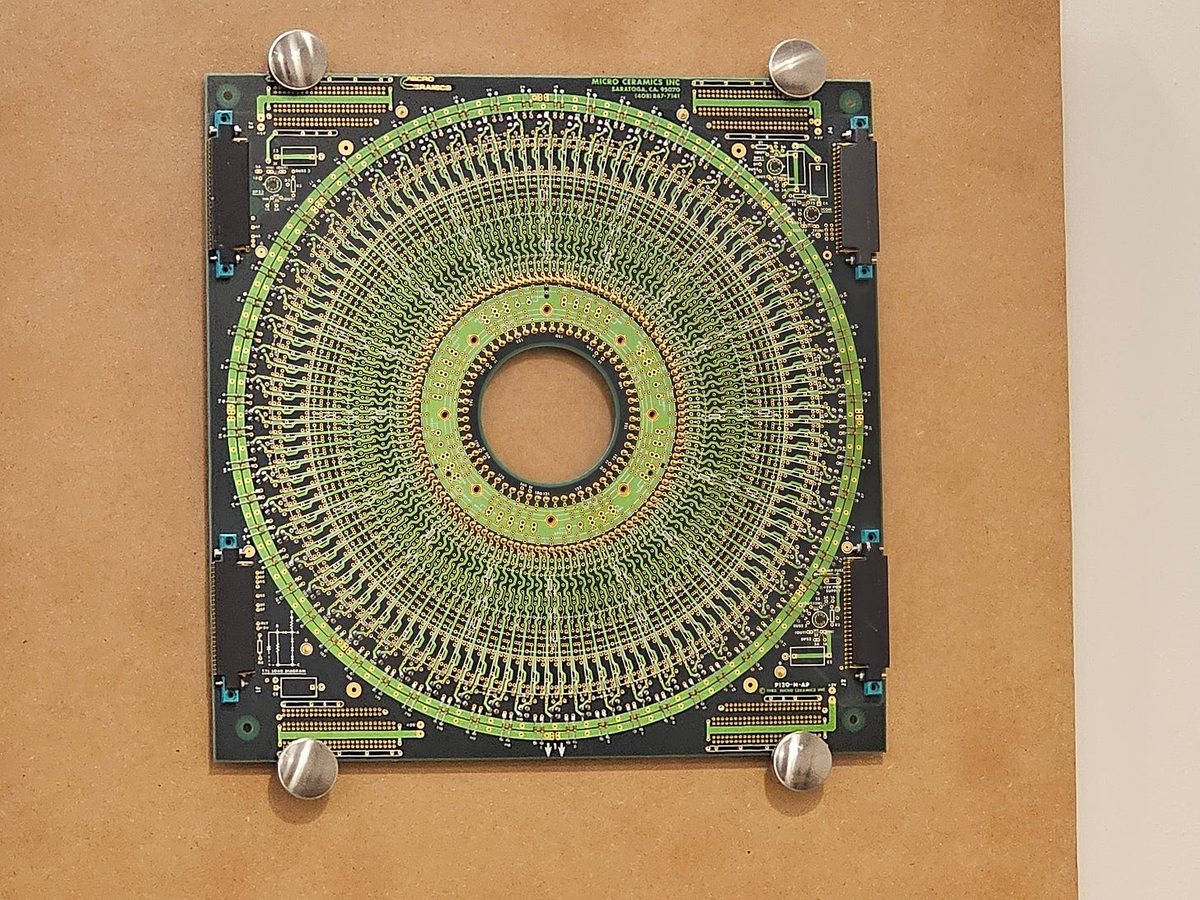
图 3|同一场发布会上的 WSE-3 晶圆与载具特写。
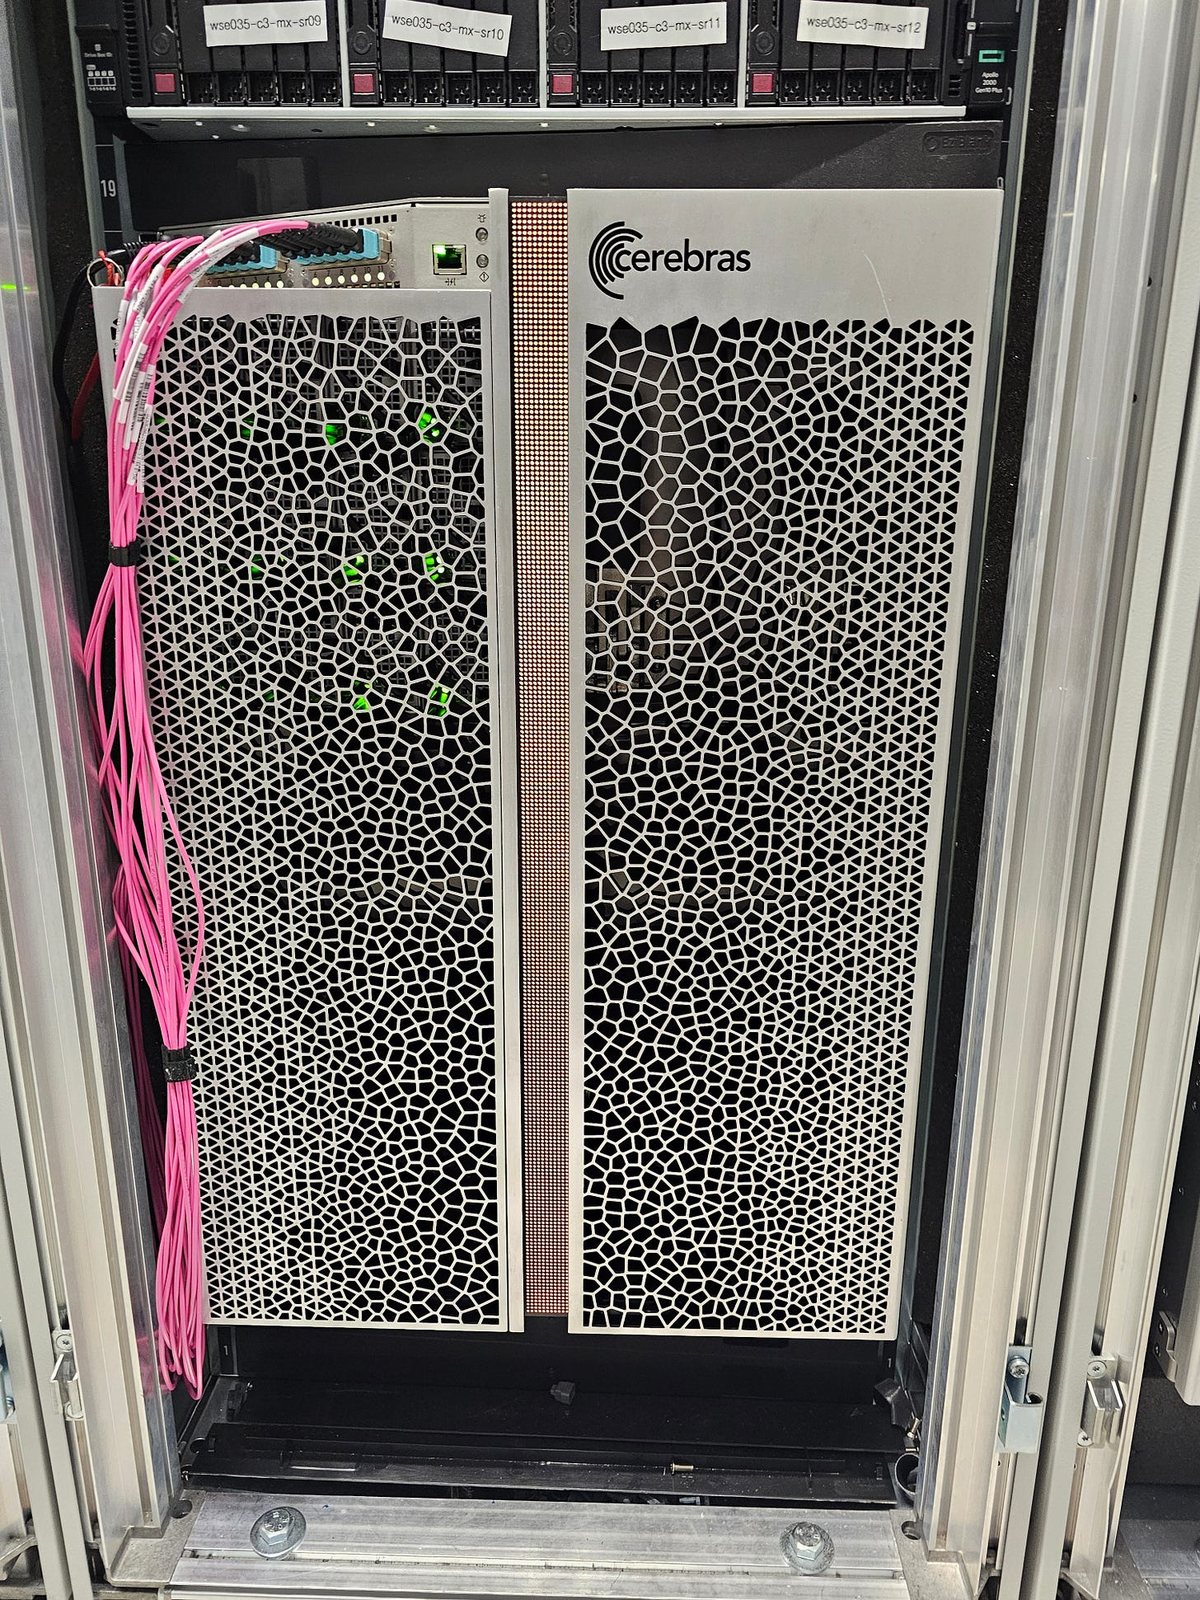
图 4|Colovore 机房中的 Cerebras 机架(正面)。
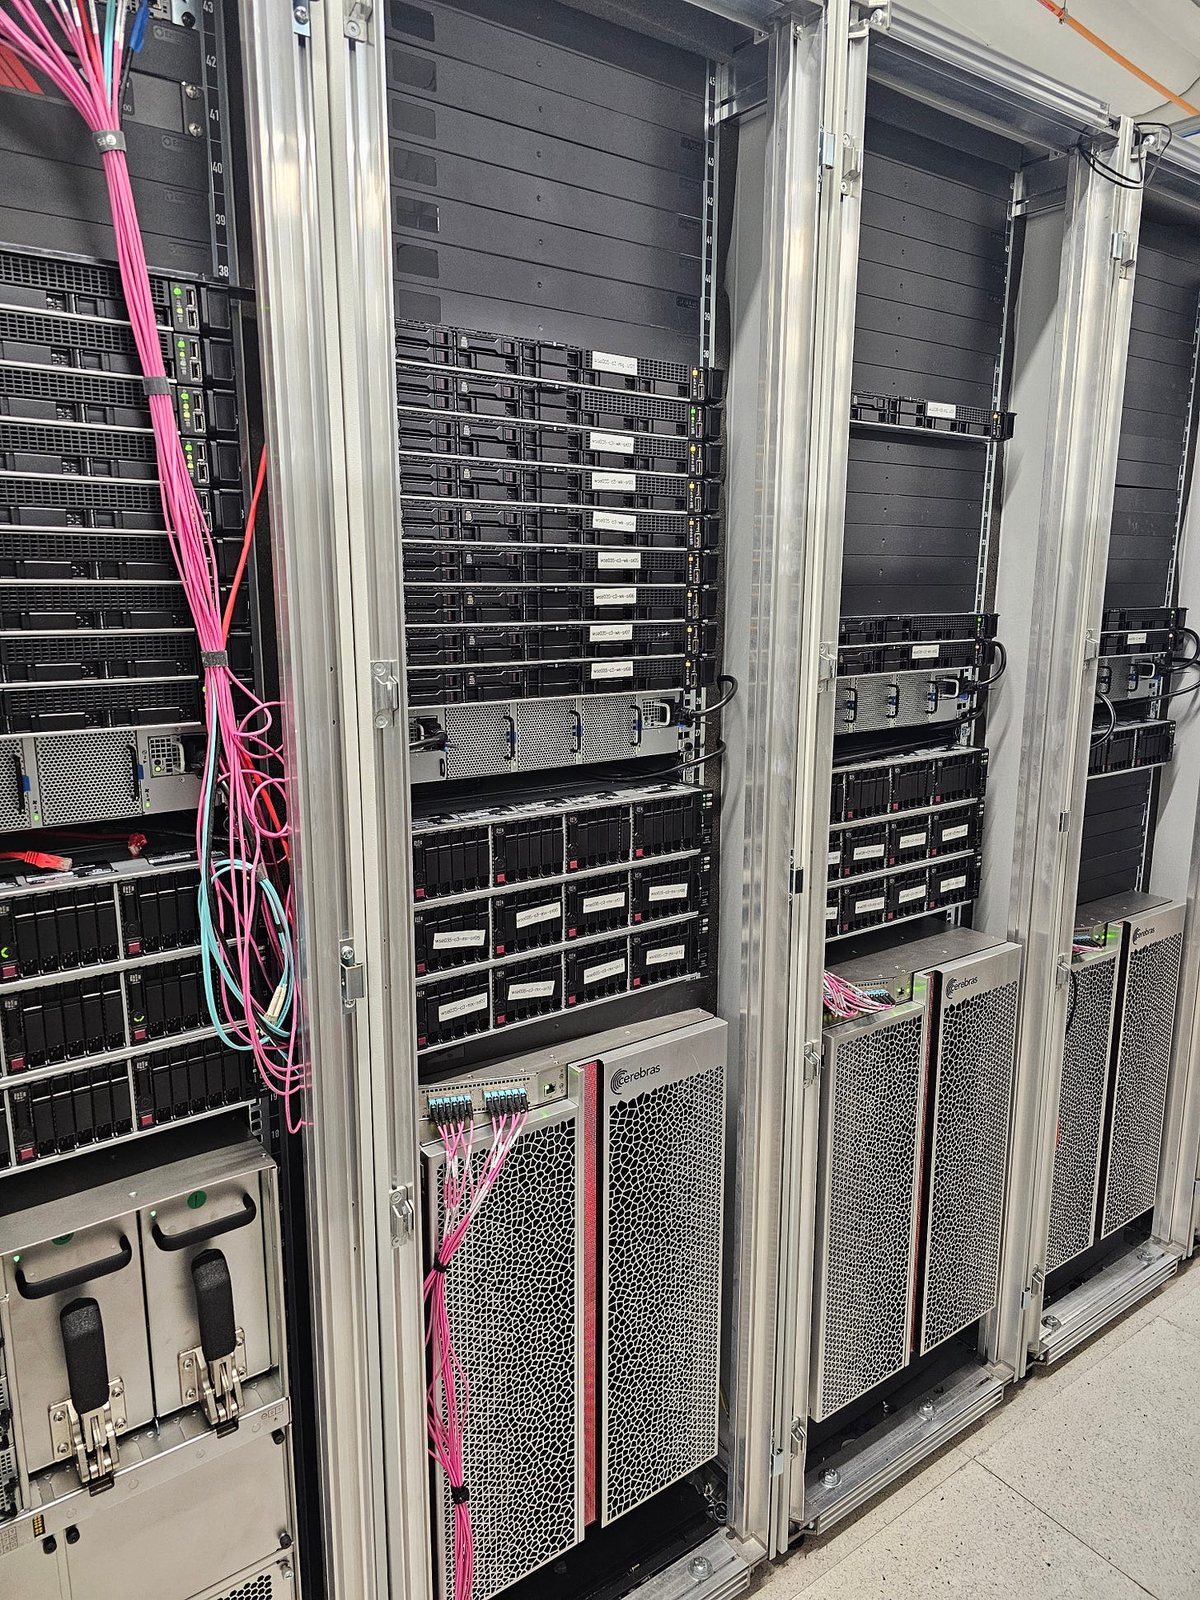
图 5|机架侧视:供电与液冷管路走向。
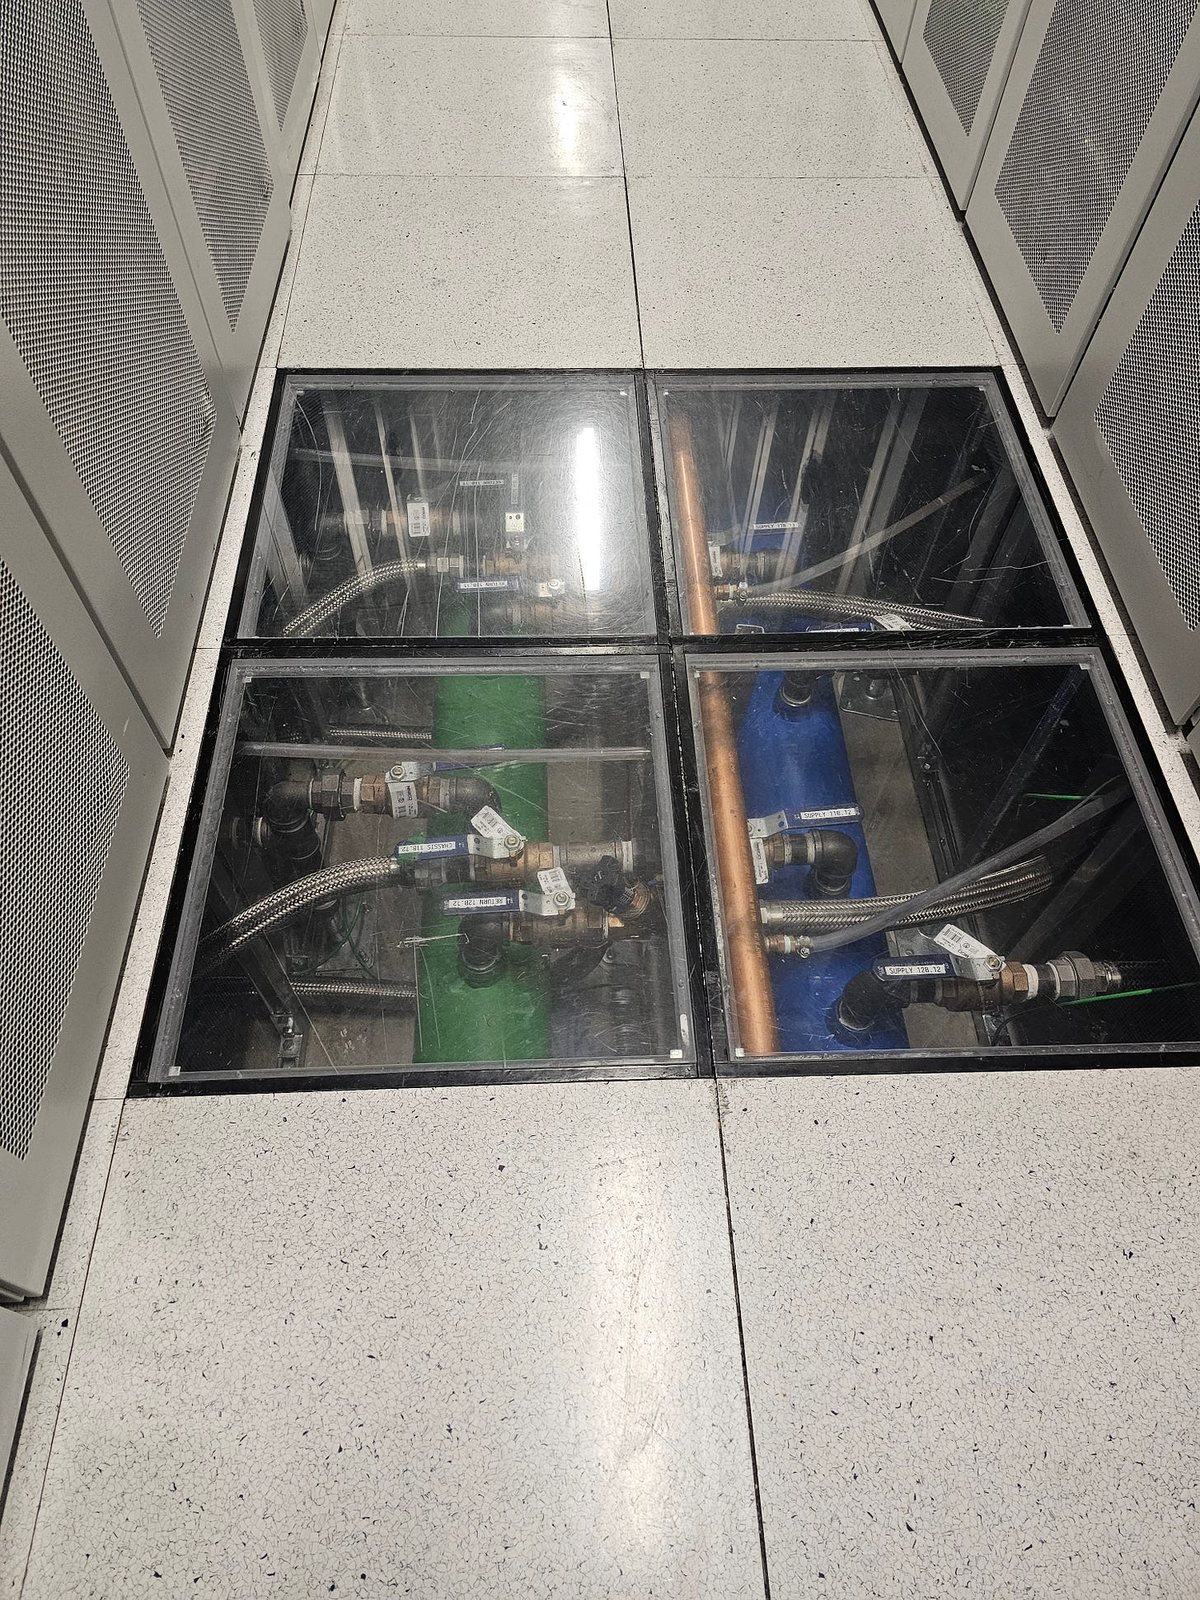
图 6|机房地板下的布线与送风结构。
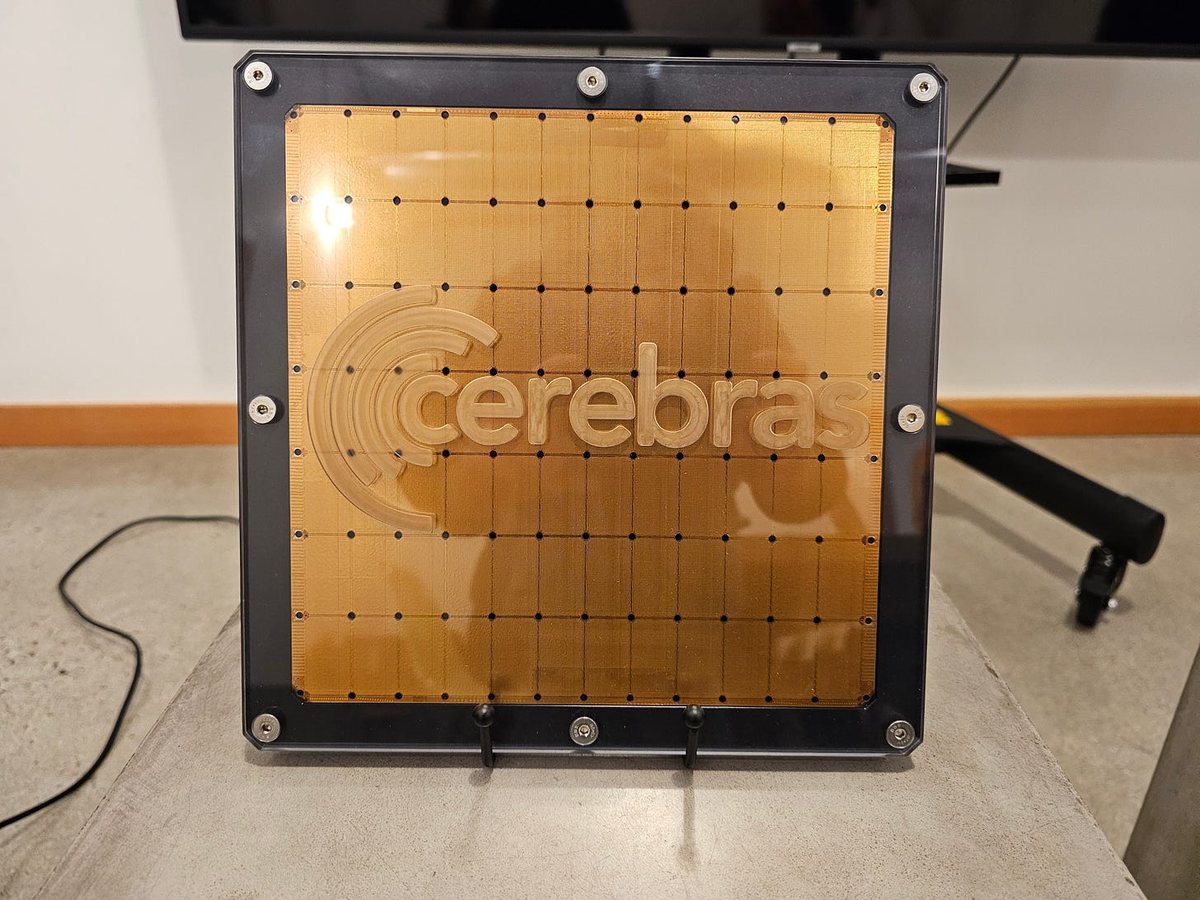
图 7|Cerebras 系统前面板特写。(原文图注:Sadly they did not let me hold it.)
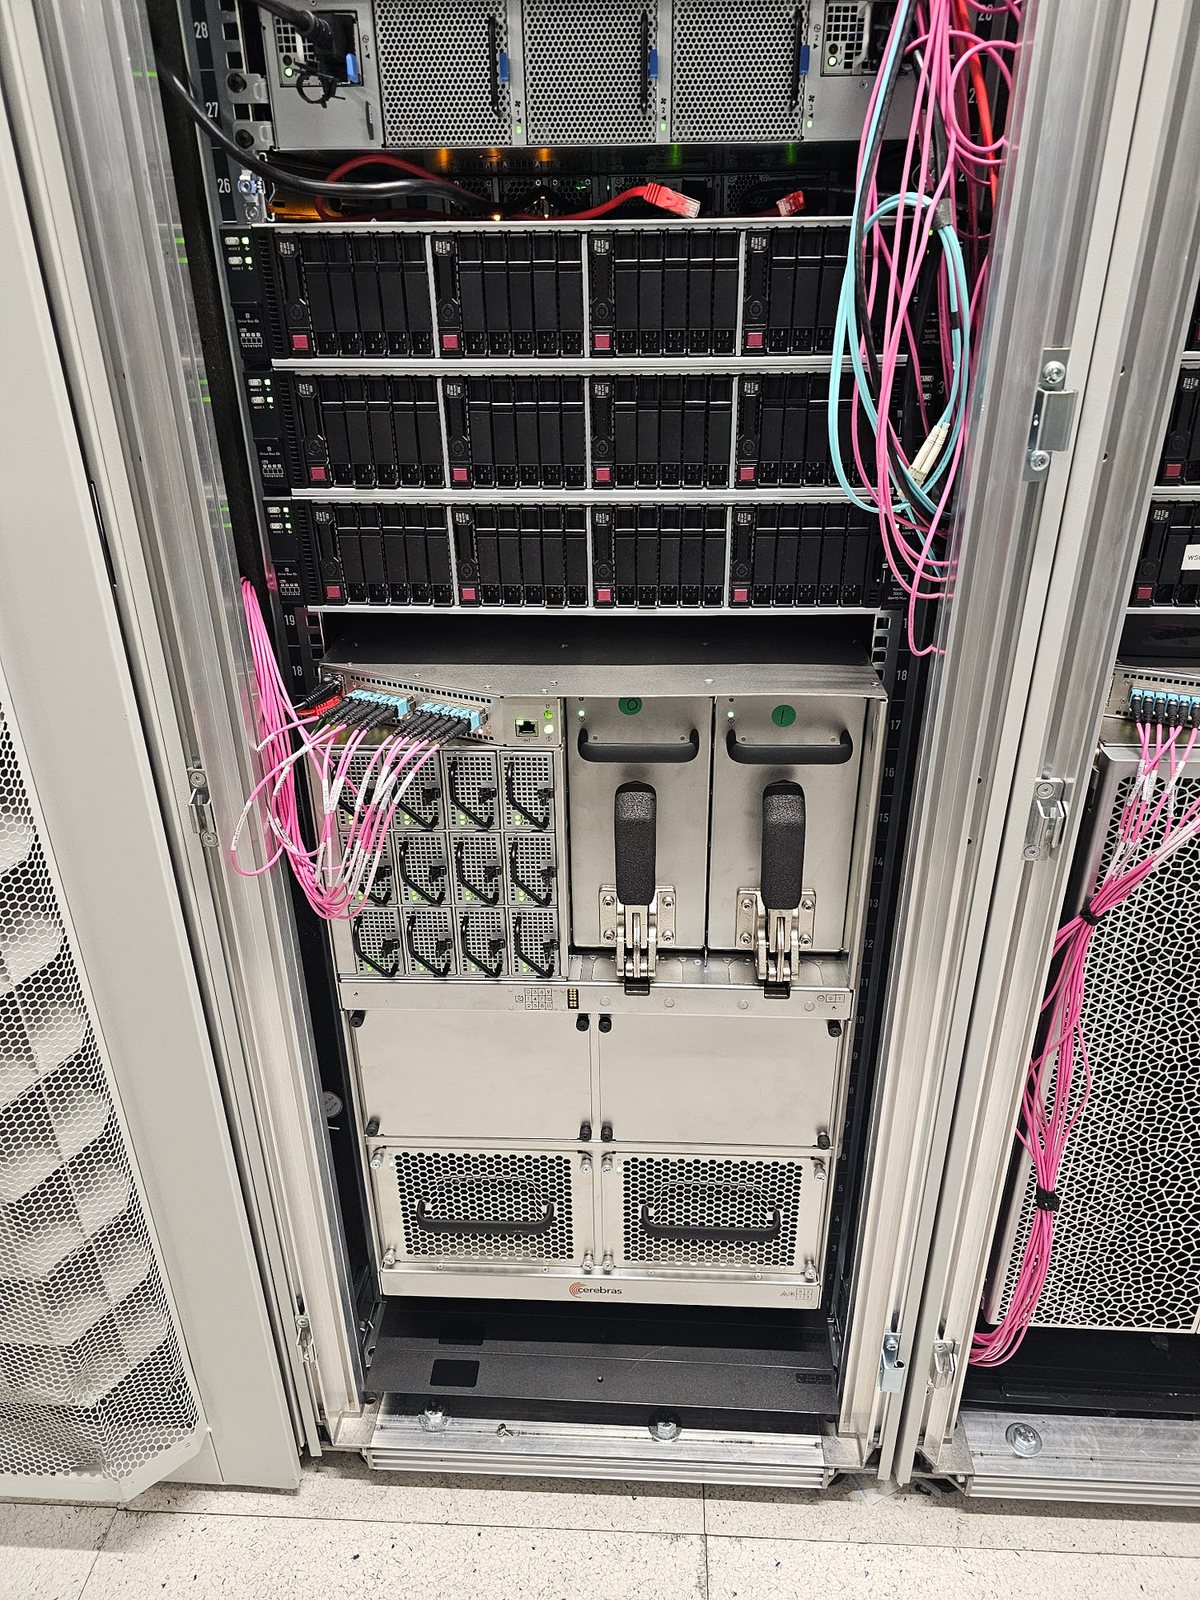
图 8|机架背面的线缆与配电。
I went into this event as a superfan but left somewhat depressed and concerend.
The WSE3 was a little underwhelming. A minor update.
What concerned me was the vibes. Andrew Feldman looked genuinely exhausted and somewhat demoralized. The Bloomberg reporter absolutely roasted Feldman. It was kind of funny but mostly sad and painful to watch.
One week later (March 19th, 2024) Cerebras held their 2024 AI day (public launch event) as a “me too hey we exist” parasite event in parallel with GTC. That event was a fucking disaster. Concentrated loser energy. Every 5-10 minutes someone on stage would say something so pathetic, I wanted to get up and leave. Unfortunately, chose a seat that made early escape from copium huffing therapy session impossible.
图 9|「SUPER COPIUM」梗图——作者自嘲式的情绪注脚。
A few months later, someone gave me slides that indicated Cerebras was trying to raise and had failed. This failed round is why the G42 deal+option happened two months later.
图 10|Cerebras 2024 AI Day 幻灯片:Investment Opportunity(2024 年 3 月)。
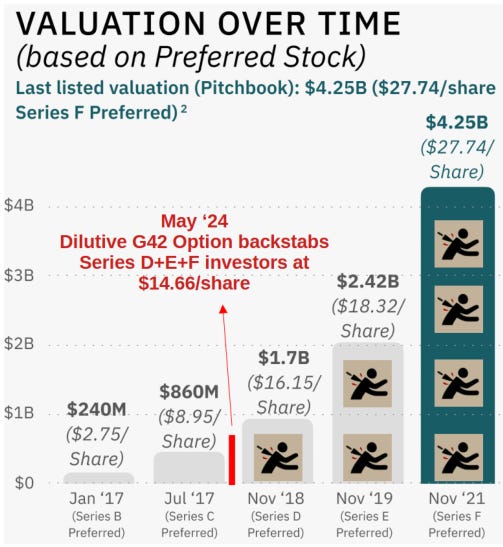
图 11|2024 年路演材料中的估值时间线(4.25 亿 → 60 亿美元区间)。
This chart in particular from their March 2024 pitch deck is hilarious.
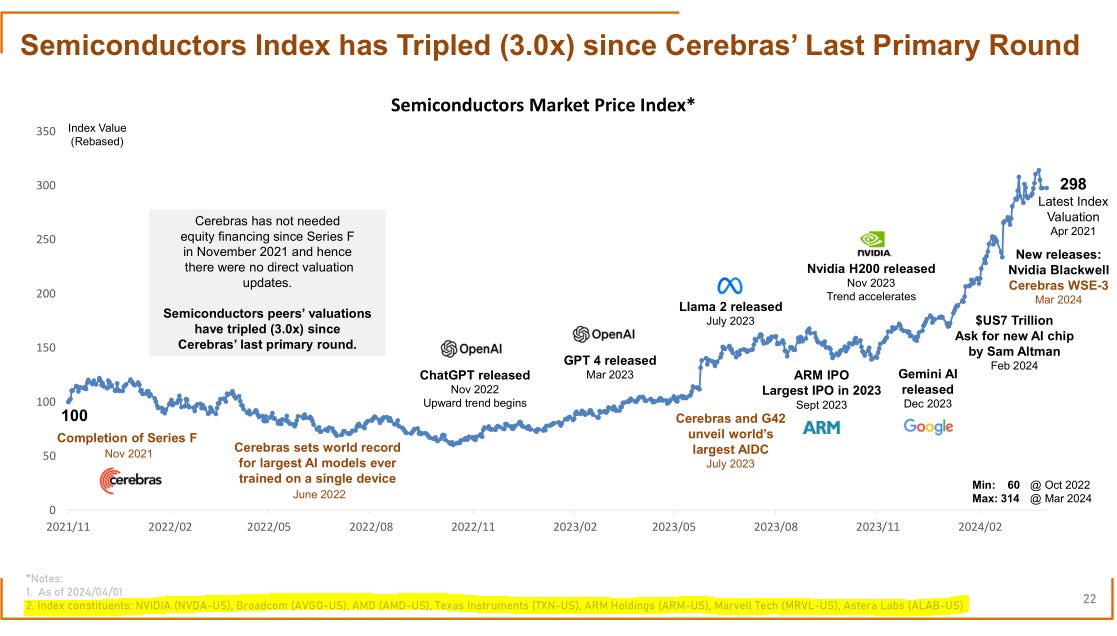
图 12|半导体指数自 Cerebras 上一轮融资以来上涨约 3 倍。
Anyway, it was around summer 2024 that I had no choice but to conclude that one of my favorite semiconductor companies was dead.
And yet, here they are today, very much alive.
Cerebras is perhaps the most controversial semis/AI stock at the time of writing. I have friends who have large short positions and large long positions. Some contacts have small long positions but keep asking me for advice on if they should size up and make Cerebras a big position. Other contacts have no involvement with Cerebras and just shit on them because they think Nvidia or various startups are better.
I would like all of you to set aside your biases, both positive and negative.
Try to be fair and balanced like me.
图 13|「Fair & Balanced」梗图——作者自称「像他一样公平客观」。
What if Cerebras the product is good, but the supply is very bad because parametric yield very bad?
Can they fix parametric yield problem and make supply good?
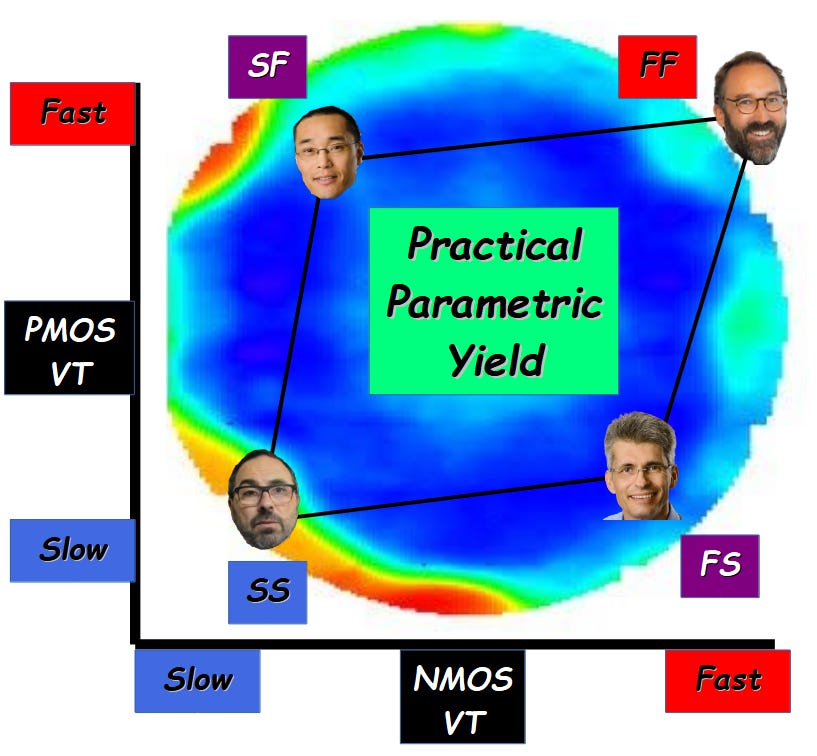
图 14|PVT 工艺边角示意:SF / FS / SS / FF 四角与 TT 中心。
Contents:
The real world is Gaussian.
Real-World Public Examples
Corners and Dartboards
Economic Choices
DVFS and TDP
Be first, be smarter, or cheat.
Cerebras unique situation, and possible outs.
[1] The real world is Gaussian.
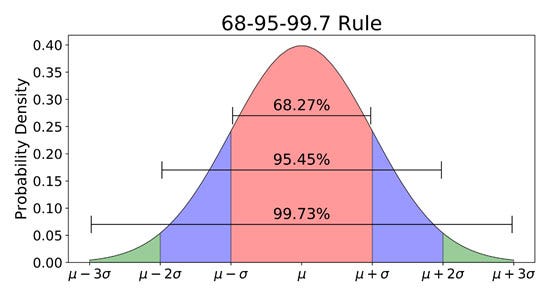
图 15|正态分布 68–95–99.7 法则——参数分布的语言。
Semiconductor design and manufacturing depends on a lot of very complex physics/chemistry and material science phenomenon. And yet, this is all abstracted out in the process development kit (PDK).
From a designers perspective, the real world (litho, etch, deposition, … variation) changes the numbers/attributes of core building blocks (devices). Transistor gate threshold, leakage power, rise time, capacitor parasitic resistance (ESR), ….
All end up as numbers in their own normal/Gaussian distribution.
Variation is natural. In order to maximize parametric yield the following typical flow is followed within industry.
Design simulates and margins circuits (analog+digital) at +/- 2 sigma process variation.
The leading-edge logic Fab (TSMC, Intel Foundry, Samsung Foundry) produces a special lot of chips called the characterization lot. These chips are run through the manufacturing line slowly and intentionally over/under doped so the process corner (+/- 2 sigma variation) is known a-priori.
Post silicon validation (my job) takes the characterization lot and figures out a unified set of default configuration parameters such that all corners pass.
Mass production begins where the process corner off each chip is not known a-priori.
Assuming everyone did their job correctly, parametric yield will be ~95%. This is the yield after defective (catastrophic yield) chips are discarded.
Of course this is over-simplified. Voltage and temperature play a huge role. This is why the acronym PVT (process, voltage temperature) is used. But as a general idea, this is how semis work in the real world. Everyone is fighting the same problems which manifest themselves as Gaussian/normal distributions.
[2] Real-World Public Examples
I think it would be helpful to cover some real examples to build your intuition before going further on the technical side. Just by looking at the SKU stack of major semiconductor companies you can see parametric yield in action.
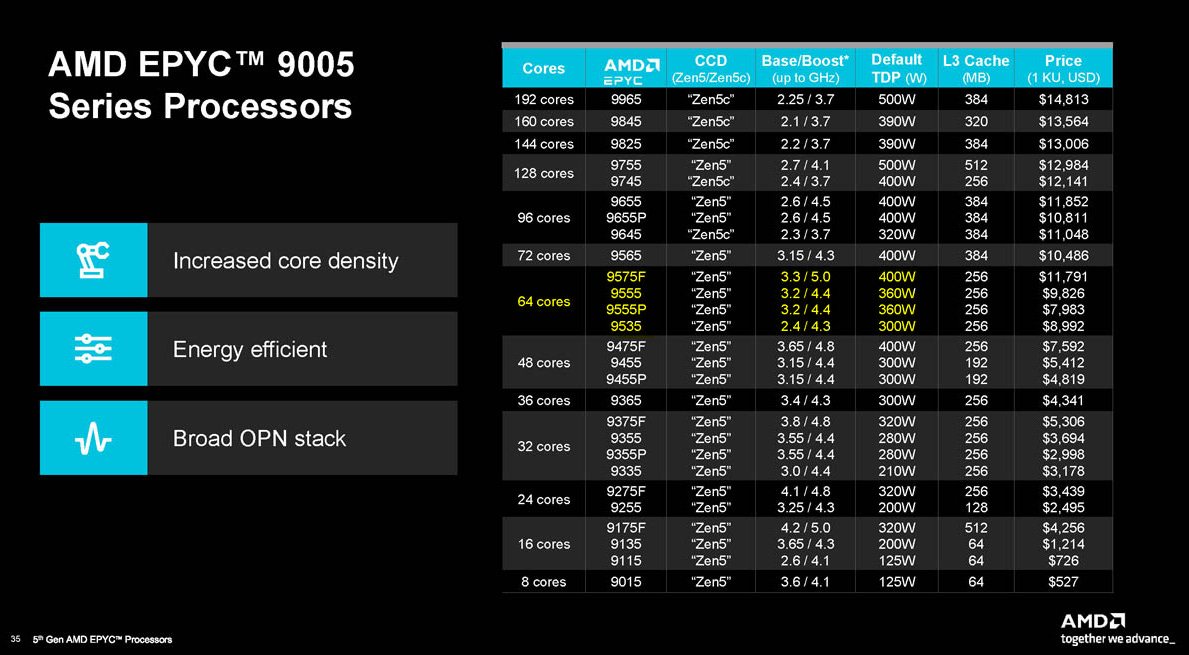
图 16|AMD EPYC 9005 系列 SKU 对照表:同一硅片、不同频率与功耗。
AMD offers four 64-core SKUs within the Turin family.
Each has a slightly different base clock (minimum speed for each of the 64 CPU cores) and boost clock (highest speed of all CPU cores assuming thermal limits are not hit). The power draw also varies quite significantly. 33% more power in the 9575F versus the 9535.
**The silicon in all these products is the same design.
What makes them different is parametric yield, not catastrophic yield.**
Catastrophic yield (defects, defect density) already determined how many cores are alive. Parametric yield determines how fast the cores run and how much power they draw.
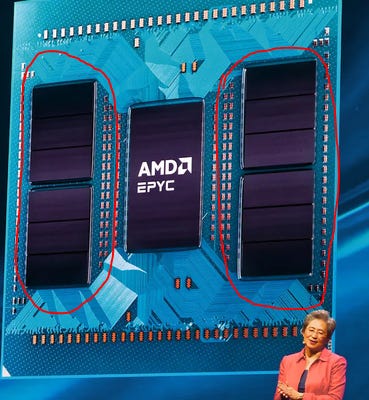
图 17|AMD EPYC 9005 芯片实物照。
You can think about this in terms of Gaussian/Normal distributions. Made up numbers because this information is closely guarded secret internal to every company….
Suppose only the top 30% of CPU core chiplet dice are “high enough quality” to make it into a high-frequency 9575F. Obviously throwing away the other 70% would be bad, so make slower/cheaper products like the 9535 with those.
This concept is called “yield harvesting” and is very common within semis. Let me show you some more examples.
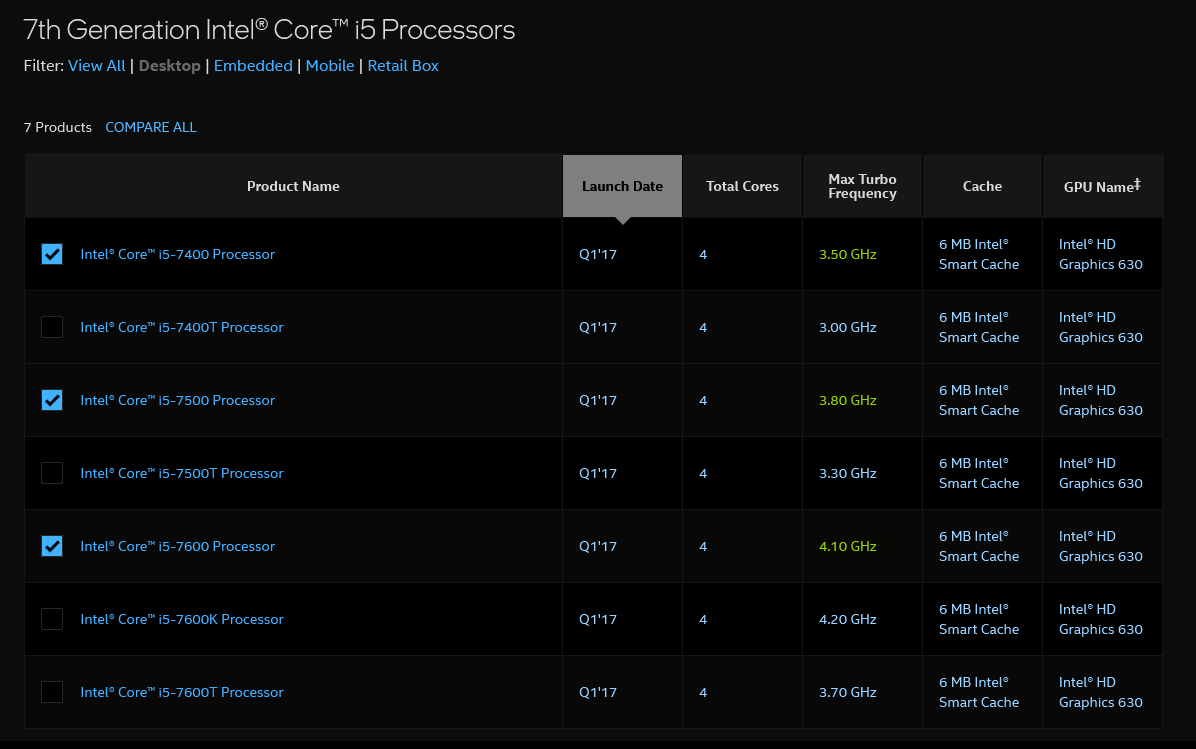
图 18|第七代 EPYC 核心与处理器规格表(含频率分档与 TDP)。
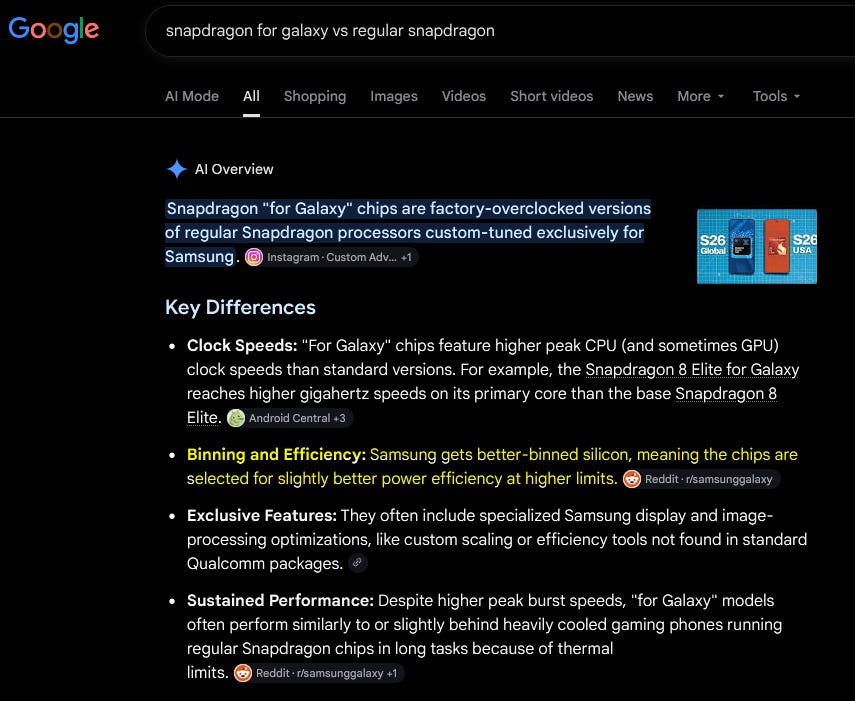
图 19|搜索结果 AI 概览:GPU 出厂即已按体质「超频分档」。
Nvidia’s gaming department (RIP does anyone care about them these days lol) has a tradition of releasing a “TI/Super” version of each GPU model around 6 months after the normal versions launch. TI/Super models are just higher bins, both in cores enabled and frequency. They need time to build up stock of the top X% of chips to supply the higher-end SKU.
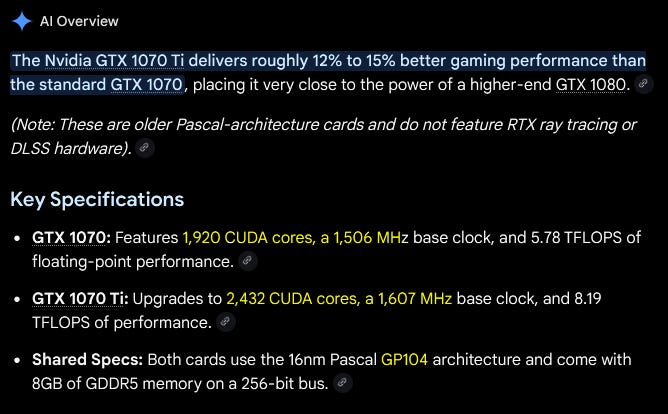
图 20|GeForce 规格对比——同一颗 GA104 设计,两个产品。(原文图注:GP104 is the die codename. One chip design, two products.)
[3] Corners and Dartboards
Process corners look like this in chart form.
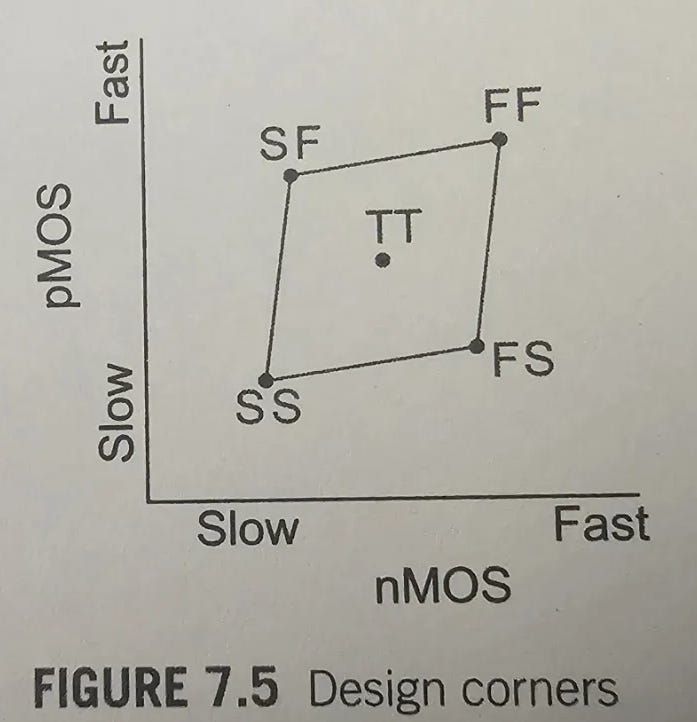
图 21|设计边角(Design Corners)图:四个工艺角在 pMOS / nMOS 速度平面上的位置。
The two types of transistors (N/P[MOS]) have varying speed in a Gaussian distribution, as all natural things should have.
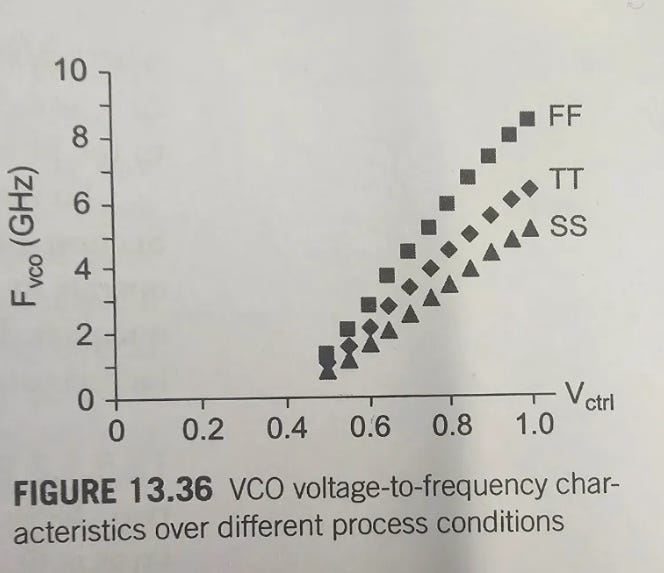
图 22|压控振荡器频率随控制电压变化——不同工艺边角(FF / TT / SS)的曲线。
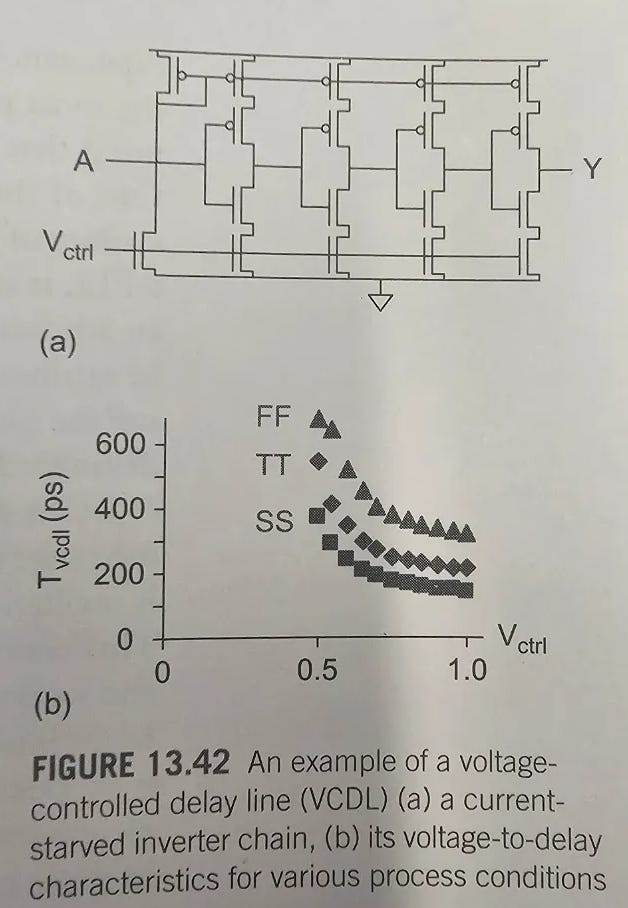
图 23|压控延迟线(VCDL)电路与延迟–控制电压曲线,含各工艺角。
Fast corners are… faster (obviously) but also kick out way more heat due to worse leakage power. So congratulations, your FF parts have a much easier time hitting target clock speed but overheat. I intentionally chose to make Gavin Baker the FF corner in thumbnail. Please clap at this clever detail.
图 24|「Please Clap」梗图。
Process corners are typically at +/- 2 sigma as a reminder.
Voltage is typically simulated at +/- 10% with respect to nominal but characterized at +/- 5%. In some cases companies choose to characterize at +/- 3% and require customers to design better power delivery to account for the tighter quoted tolerance. But designers always simulate at +/- 10%.
Finally we have temperature where there is a lot of variation depending on the company and product end market.
Standard corners are -20C and +110C.
Extended corners (automotive, industrial, military) are -40C and +125C.
A popular reduced range is 0C to 70C or 90C.
Imagine all of this corner stuff as a dartboard.
High-volume manufacturing is the logic Fab throwing darts while blindfolded. The system integrator (entity that buys the chips and makes motherboards, racks, laptops, smartphones, whatever) is responsible for power delivery and thermals. They too have their own dartboard due to variation in power delivery components and thermal/mechanical tolerances.
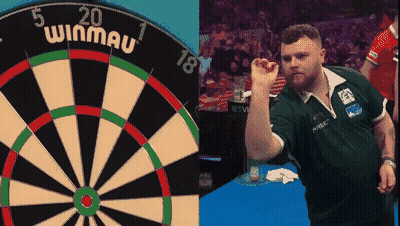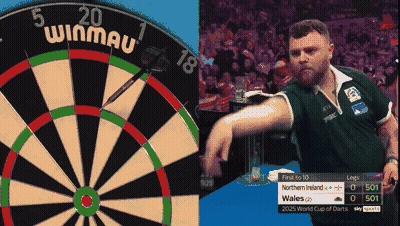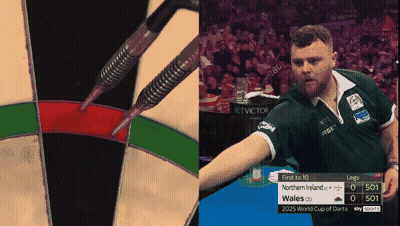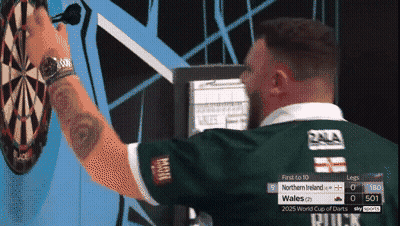
图 25|盲投飞镖——量产的工艺角在投出之前并不可知。(原文图注:TT, TT, TT, lets gooooo!)
If you build millions of something complex, there will be meaningful variation. The trick is to bake enough margin across the stack (PVT) such that your parametric yield (and thus economic outcome) is economically optimal.
[4] Economic Choices
I find it very irritating when people take engineering sample leaks as gospel.
At what corner is that engineering sample from…? You don’t know? Well then shut the fuck up this is useless information.
At the end of the day, clock speed is a choice, not by the designers.
This trips a lot of people up. It seems a lot of people have an intuition that designers target a clock speed and that is the goal.
In reality, clock speed is an economic/business choice.Post-silicon validation figures out what reality looks like and product management (business group) decides the final clock speeds and SKU stack.
Sometimes things go wrong. Two famous examples are AMD RX Vega (which got Raja Koudori fired from AMD) and Nvidia Ampere Gaming (RTX 3000 series).
图 26|某芯片项目的「目标 vs 实际」主频幻灯片。
To understand what happened with these two product lines, you need to understand these two charts.
First, the Schmoo chart.
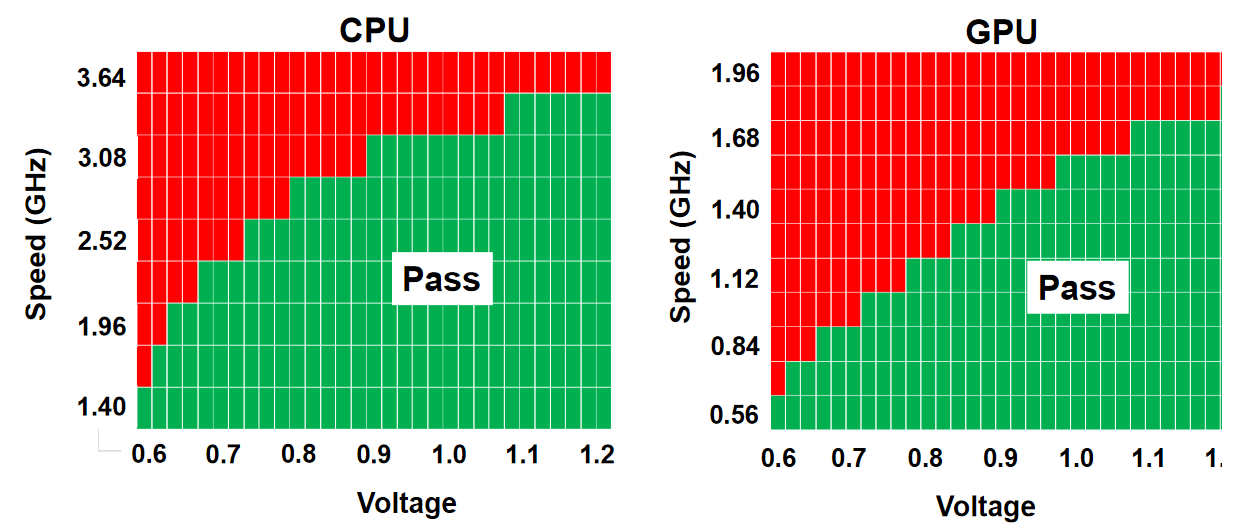
图 27|CPU / GPU 的速度–电压 Pass / Fail 分区图。
More voltage means more heat generated. Every chip has one of these curves.
The same data can be plotted like this.
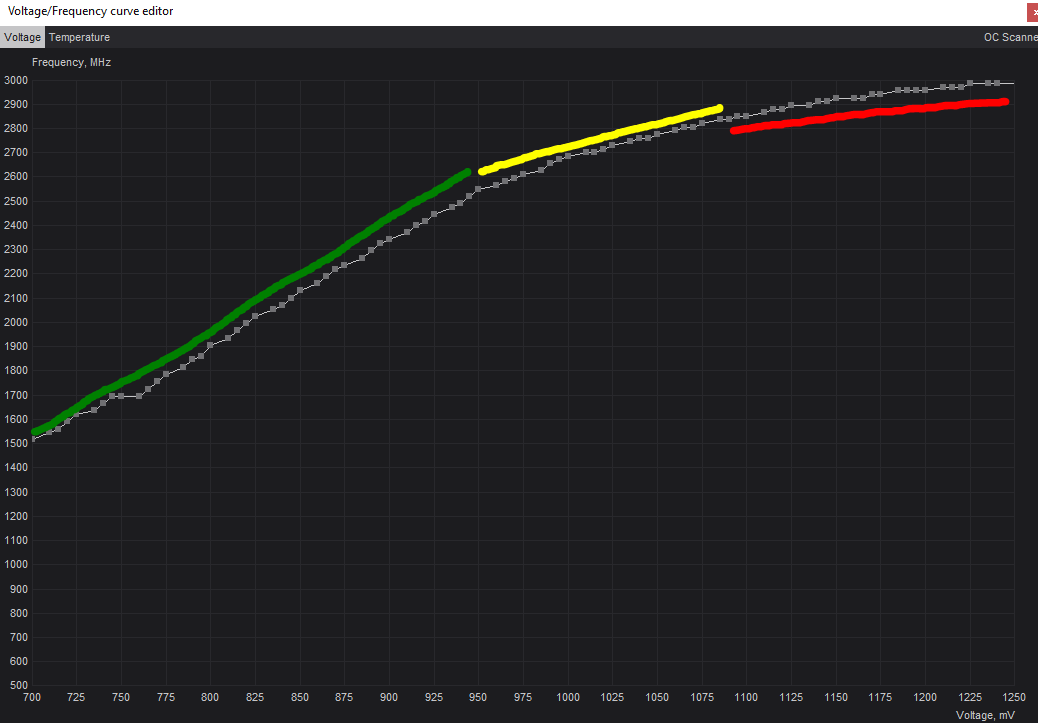
图 28|单颗芯片的电压–频率曲线。
In general, most chips have this three-region response in voltage versus frequency.
First a linear region where you get good gains. Then a region where there are diminishing returns. Finally a region where you shove huge amounts of power and get almost nothing for it.
In general, products are targeted at the edge between green and yellow region, with some opportunistic boosting into the yellow region.
What Nvidia Ampere Gaming (3000 series) and AMD Rx Vega have in common is both were factory shipped deep into the yellow region and in some cases into the red region.
Remember, clock speed is a choice. Design, marketing, product management, and competitive analysis groups had a set of goals. Gaussian reality, conveyed by post-silicon validation group, resulted in unexpected changes to the plan.
When reality becomes severely disjointed from the original plan, it means someone fucked up badly. Modern EDA tools are quite good.
In the case of Nvidia Ampere Gaming (3000 series) it was Samsung Foundry’s fault.
In the case of AMD Rx Vega, it was Raja Koudori and his mis-managed design group’s fault.
[5] DVFS and TDP
Dynamic Voltage Frequency Scaling (DVFS) is a very common strategy that has a lot of potential complexity in its implementation.
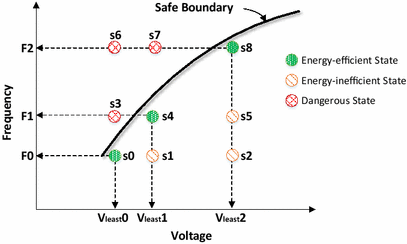
图 29|「安全边界」工作点图:绿点为能效状态,红点已进入危险区。
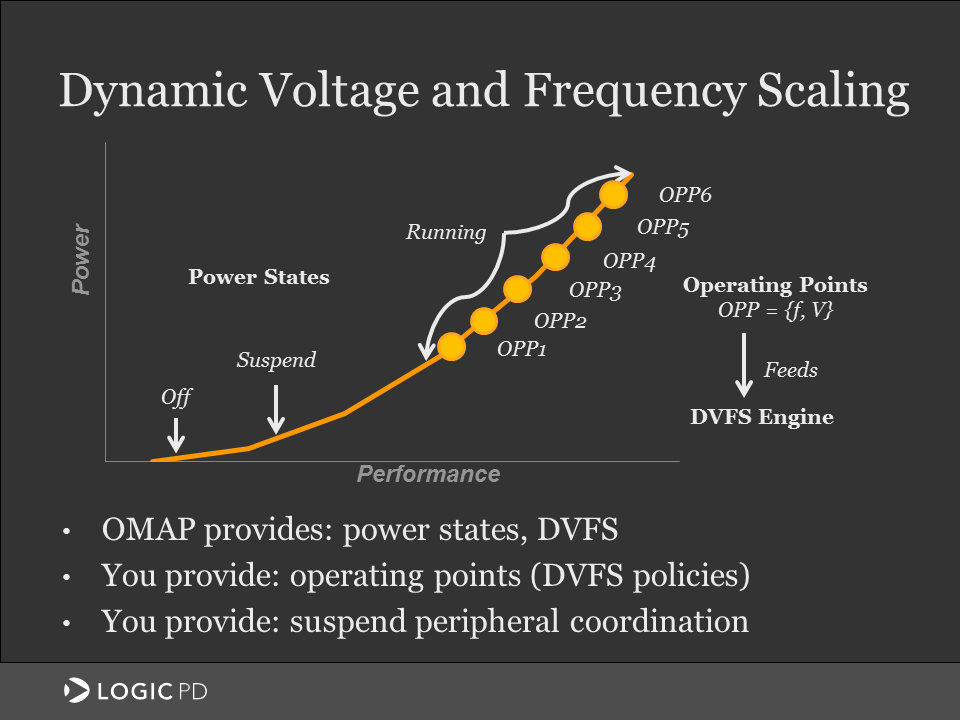
图 30|DVFS 原理幻灯片(TI OMAP):功率状态与工作点选择。
TDP stands for thermal design power. This is the maximum sustainedpower a chip can draw because the cooling is built around this maximum.
I made “sustained” bold because peak/instantaneous power can (and regularly is) be much higher.
Chips have many internal sensors. Only a small subset of which are exposed to end users. Lots of hidden goodies locked behind encrypted and obfuscated firmware and fused off registers.
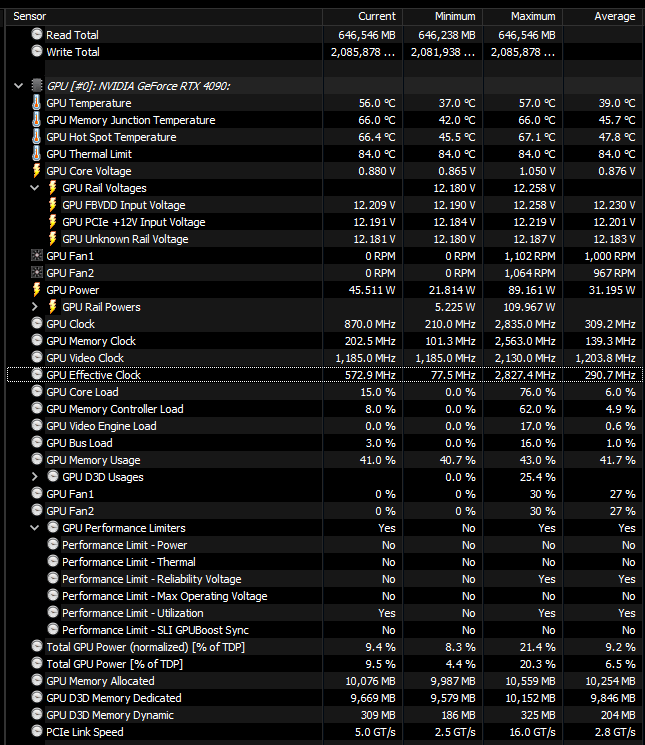
图 31|芯片内部传感器 / 寄存器转储(一)。
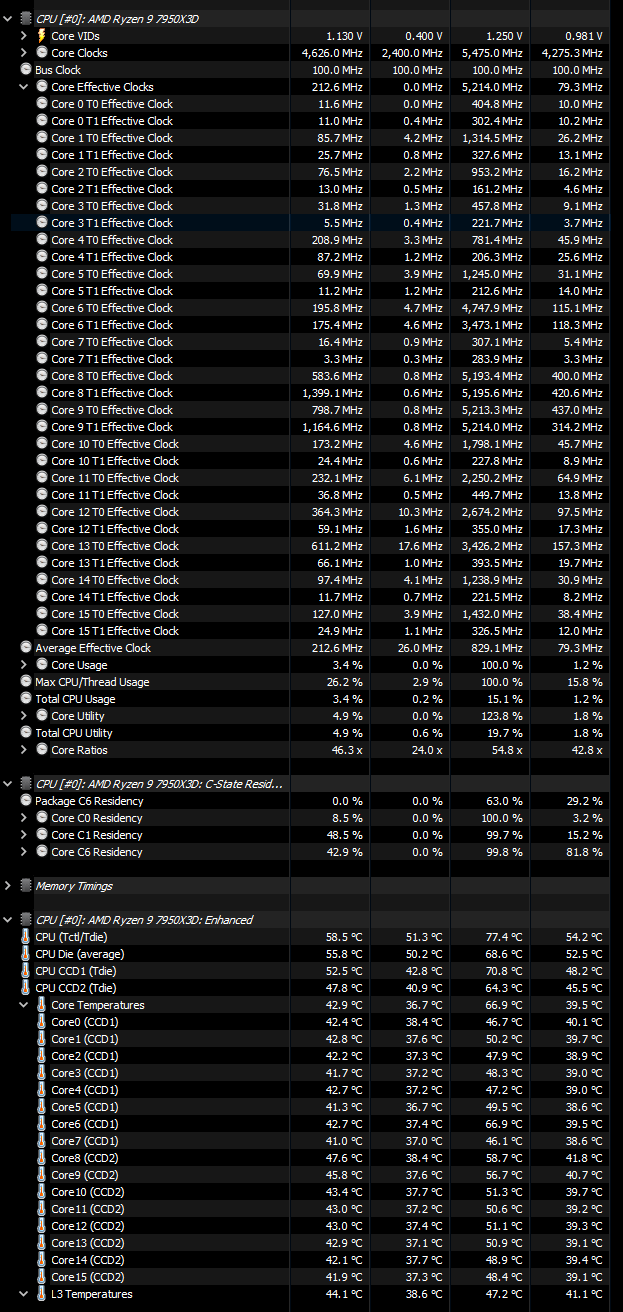
图 32|芯片内部传感器 / 寄存器转储(二)。
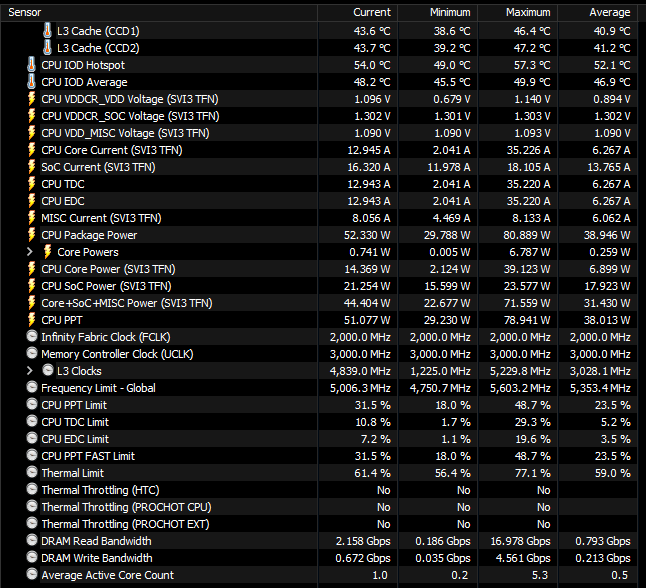
图 33|完整传感器读取表:温度、电压、电流、功耗、频率。
To help build your intuition, let’s look at a generalized scenario.
You have a chip with the following attributes:
TDP of 100W
10 different blocks (CPU core, systolic array, polynomial engine, SIMD engine, whatever)
1000 sensors (temperature, voltage, counters, busy/open signals, utilization, …)
The objective is to maximize performance while staying within sustained power, peak voltage, and thermal limits.
“Maximize performance” could mean absolute performance or performance/watt. Depends on your goal. Often this toggle is exposed to users or at least end customers.
(See Nvidia MAX-Q vs MAX-P)
This puzzle is a lot more complicated than you think.
What if a workload stresses “block X” much more than the other blocks? You will get a hot spot.
What if the system ends up more efficient in a “race to idle” scenario in which DVFS pushes the chip into an inefficient state but for a shorter period of time?
How to allocate power budget across blocks?
And remember… PVT variation (PARMATRIC YIELD) is still around, making this problem much more difficult and varied.
[6] Be first, be smarter, or cheat.
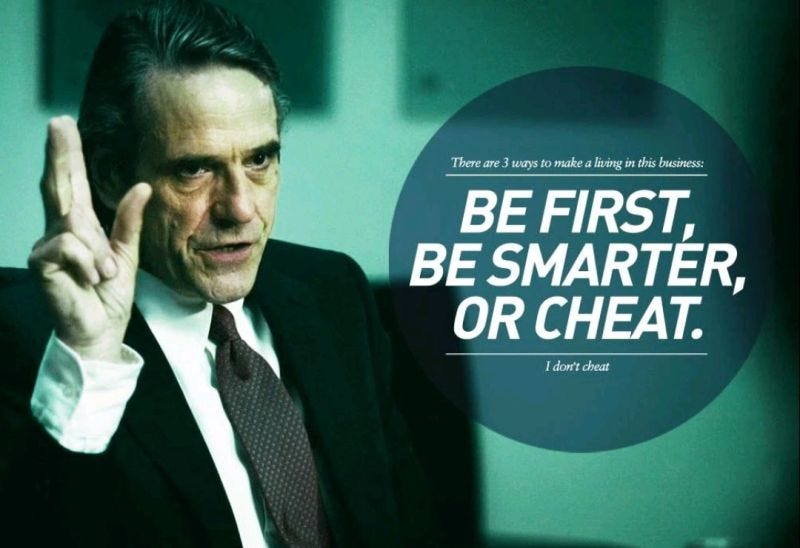
图 34|《Margin Call》台词:「BE FIRST, BE SMARTER, OR CHEAT.」
Semiconductors is a ruthless industry. Miss a product window and the competition will cut your throat ear to ear.
Much like one of my favorite Margin Call quotes, there are three ways to make a living in this [semis] business.
Be first.
Be Smarter.
Or cheat.
The thing about semis is, this world is largely self-policed because cheating is very easy and the only way to find out (for sure) if someone lied to you is to get volume samples to independently test.
To understand what I am talking about, let me give you some real examples, some of which are heavily obfuscated for obvious reasons.
图 35|《赛博朋克 2077》内的 NDA 物品卡——「禁止很多、回报很少」。
Lasers are typically (almost always…) run at 40C die temp or higher. Lumentum’s public UHP demo at OFC 2026 was at 30C. This information was disclosed in their laptop monitoring tool in small font while the headline numbers (optical output power, efficiency, RIN, linewidth) were in big font and on the slideshow TV.
At DesignCon 2025, Marvell had an optical DSP demo (3nm, 1.6T) that had very aggressive cooling.
Same conference, Alpha wave had a PCIe 7 live demo showing 1e-12 BER (very good) but at a relatively short channel. Meanwhile the marketing materials discussed support for much more lossy channels.
There was a time where I was debugging a performance issue and found a register that would juice a small sub-circuit bias voltage and deliver significant performance gains. The overall power draw of the chip and thermal dissipation were the same.
When I shared my results with design, one of them had a visceral negative reaction and demanded I never use this register again. Apparently, it was included as an emergency debug feature. Leaving that register enabled would lead to catastrophic electromigration issues. Essentially the chip would fry itself after a few months.
Think about what this kind of situation enables.
I could have kept that register enabled and lied to my manager.
My manager could have ordered me to use the register anyway for marketing and test reports but disable it in customer firmware. When the customer realizes performance is worse than the report, too late they already committed to purchasing the product and cannot switch.
A single person, even a low-level IC, has the power to commit significant fraud. This is common simply because of how complex semis are and how easy it is to hide things from other internal departments and cheat.
(we did not use the register… took me a couple weeks to find a safe solution)
There was a time when a competitor was telling (shared potential) customers very unsafe and unethical things about undervolting.
As a reminder, designs are almost always simulated at +/-10% and characterized at +/- 5%.
The competitor (same product class, same process node) was quoting -18% voltage as safe and viable.
Marketing and upper management of <former employer> placed enormous pressure. My former manager instructed me on how to safely determine what undervolt we could commit to without being unethical. After a month of work, the result was a -12% or -14% depending on some nuance. My former manager wanted to be safe and decided to pass along power numbers at -10% to be conservative.
Word of advice, this industry is built on reputation. If you are consistently asked to do potentially unethical things its time to find a new job. It will greatly benefit your short-term sanity and long-term career opportunities.
People know who worked at which company on which group/project.
图 36|「Word gets out」——这行的名声会传播。
Word gets out.
You will never sell anything to any of these people ever again.
Remember that job interviews are you selling yourself (your labor).
Cherry-picking is a common practice. If a company is demoing some chip at a conference, they are not going to pick an FF or SS part. Of course it will be a TT part.
But suppose you have a tray of 100 TT parts. Are you going to pick a random one?
No… you will pick a subset of TT parts to test and use the best one.
Is testing 5 TT parts and picking the best ethical? Sure its marketing.
How about testing all 100 TT parts?
There exists a line between reasonable marketing/promotion, and cheating.
There exists another line between cheating and fraud.
Do I sound like someone who knows how to cheat and spot cheating? These are highly correlated skills.
One of my (unusual) hobbies is to watch police interrogations. I sometimes copy their strategies. Start with some soft and friendly questions to make the target feel safe. Then abruptly pummel them with sharp, specific questions. Cut them off and don’t give them time to think. Latch on to their mistakes.
You would be surprised at how many people crumble under pressure and give away key details.
This brings me to the 25% B0 Jalapeno clock speed comment by Semianalysis.
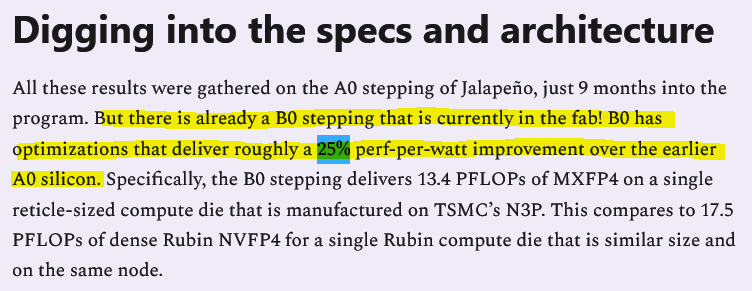
图 37|SemiAnalysis 关于 OpenAI Jalapeño 规格与架构的段落(含 B0 步进主频高 25% 的说法)。

图 38|OpenAI Jalapeño 徽章。
This is an absolutely massive red flag. It’s a red flag that is on fire in an incandescently bright manner.
A 25% delta in perf/watt (optimum point on volt/freq curve) going from A0 to B0 means catastrophic failure. SA passing along this detail without realizing or discussing its significance is a huge miss. This detail is so huge, nothing else matters.
Something went seriously wrong with Jalapeno. As far as I am concerned, A0 is broken and parametric yield must be an unmitigated disaster. This is the opposite conclusion/narrative of SA.
Remember, designs are simulated at +/-10 voltage corners and +/- 2 sigma process corners.
If your clock speed is off by 5-10% (A0 vs B0, or A0 vs target) after characterization and tuning, then that is a modest mistake.
Off by 15% means something severely went wrong.
**Off by 25% is a disaster and might as well be off by 50%. Someone fucked up badly in this scenario.
Catastrophic. Failure.**
In this case, the foundry is TSMC N3P, the worlds second best leading-edge logic process node and PDK. N5/N4P PDK is worlds best. N3E/N3P had some minor regressions in PDK quality two years ago which have since been mostly fixed.
So either Broadcom fucked up or OpenAI (+ the AI agents who vibe-coded all the RTL in “record time”) fucked up. I will leave it to you to come to your own conclusion on who is responsible for the Jalapeno A0 disaster.
[7] Cerebras unique situation, and possible outs.
Parametric yield is an industry-wide problem. Cerebras is disproportionately affected.
It’s not their fault. It is a logical and natural consequence of their core technology, wafer-scale compute.
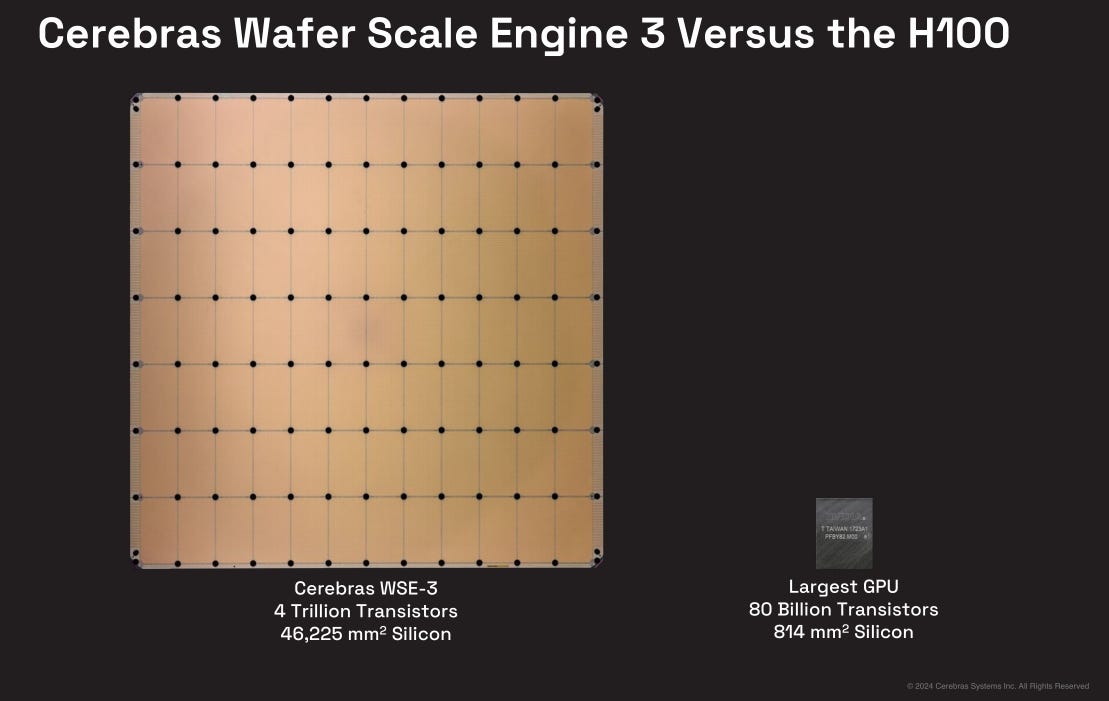
图 39|WSE-3 与 H100 的尺寸对比。
Engineering is about tradeoffs. Nothing is free.
Most AI accelerators are built with reticle-sized dice that can be tested and characterized before advanced packaging. So most of parametric yield and tuning work can be done at a die level. Most, not all. There is some variation in advanced packaging parasitics.
Cerebras has to effectively get good parametric yield on 84 reticles on the same wafer.
Remember, the normal strategy’s every other semiconductor company uses for parametric yield are:
Throw away chips that are too slow or run too hot. (Cerebras can’t do this)
Sell lower quality chips as a different SKU. (Cerebras can’t do this)
Change various registers and settings of each chip to tweak and get most of them to pass spec. (Cerebras might be able to do this in a limited way… more on this later…)
What makes this situation much worst for Cerebras is test flow.
Every logic wafer is tested at a wafer-level using ATE machines (Teradyne, Advantest). This stage of testing is really for basic diagnostics and to find out which chips are healthy enough to package. Packaging is expensive.
System-level (packaged part) testing is absolutely critical for tuning and to figure out which devices are good enough.
The penalty for throwing away a bad (failed parametric yield) packaged GPU/ASIC (normal ones) is bad but not disastrous. Yes it hurts throwing away 1-2 reticle-sized logic chips and 4-6 HBM stacks and some CoWoS-L wafer area. But you can set up a socketed test rig and avoid throwing away power delivery, PCB and other stuff and assembly cost (money and opportunity/time cost) is not that bad. Modern thermal heads and test rigs are pretty good.
Cerebras gets killed by all of this. They have to package the wafer with all the expensive custom vertical power delivery and bespoke cooling into the final product. There is no real test rig. At least no test rig with economics and usability anywhere close to those for normal chips.
You can see this from the OpenAI Jalapeno test rigs.
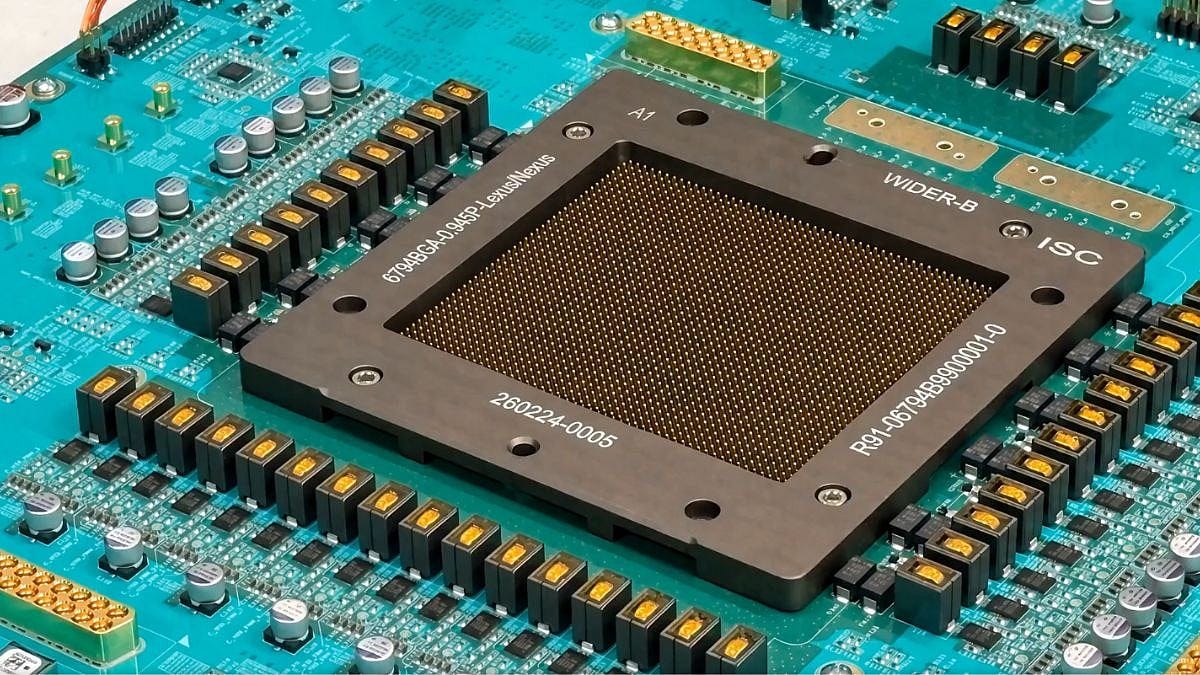
图 40|Jalapeño 的插座式测试板。
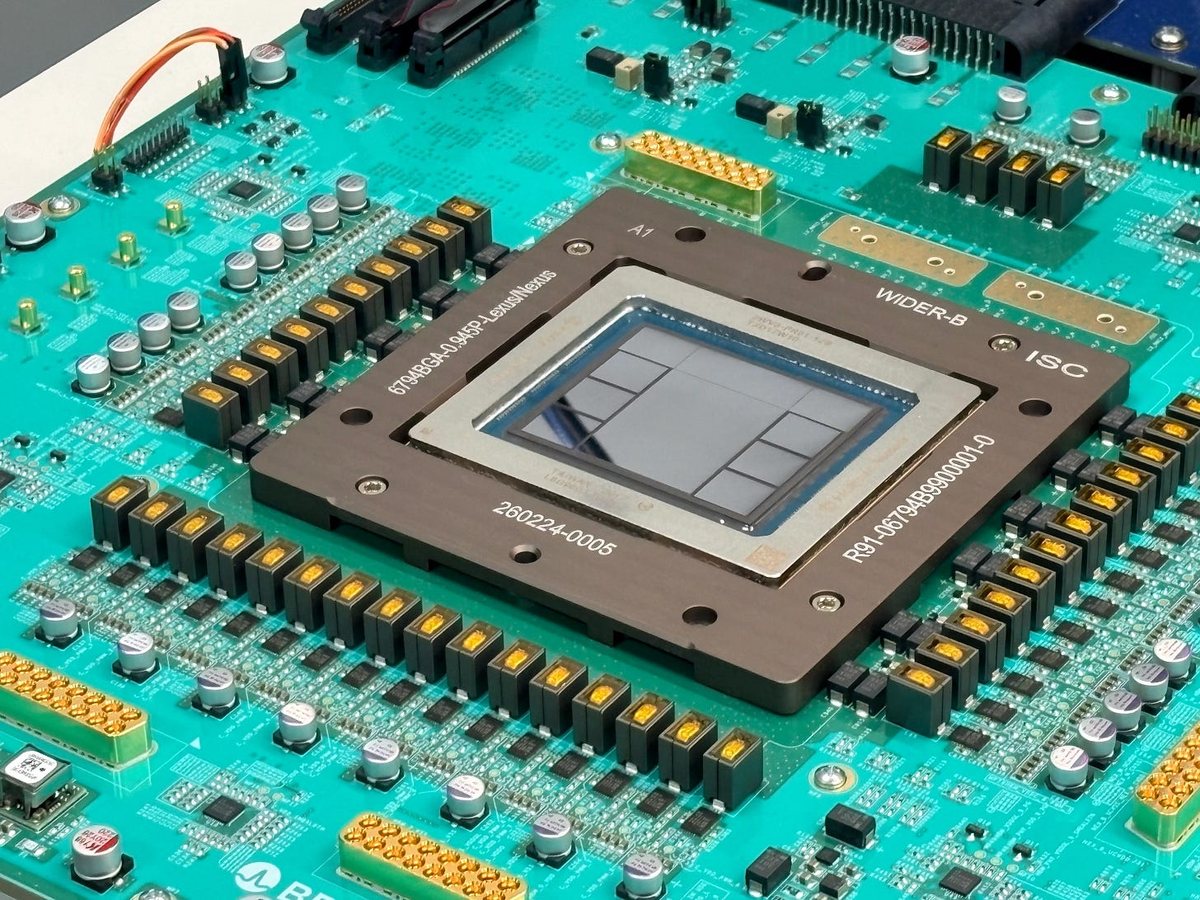
图 41|Jalapeño 封装特写。
Socketed PCB. Easy access to jumpers and diagnostic pins. Over-built power delivery to run DVFS experiments. Easy IO diagnostics with Samtec Bullseye connectors. And an automated vertical thermal head (not shown, I am assuming) for thermal sweeps.
It matters a lot having the ability to set chips to specific temperatures to evaluate performance and debug timing issues.
Cerebras is so limited in how they can test and deal with parametric yield. It’s a very difficult problem I am not criticizing them. Just pointing out how severe the problem is because of… reality.
I want to frame this section is a particular way.
Cerebras was founded in 2015.
The first WSE was released in 2019.
The current generation WSE3 was released in 2024.
An updated enclosure for WSE3 (significantly better power delivery and cooling) was released in 2026.
Suppose you reduced Cerebras down to 10 “dangerous/existential” problems.
How to get cross-reticle stitching to work?
Vertical power delivery and cooling.
Graph compiler.
…
…
…
blah blah blah.
Obviously, they had to prioritize which dangerous problems to work on. What to fix first and how much effort.
I believe that parametric yield is the problem that has gotten the least attention from Cerebras.
Again, this is not a criticism. These guys had to prioritize and deal with limited resources.
From my conversations with Sean and JP, it really seems like after all these years, they have only just started to seriously look into parametric yield.
One of the most obvious strategies is to give each reticle on the WSE it’s own voltage or even go further and give parts of each reticle their own voltage domain.
Sean has been repeatedly very evasive when I ask about this. My guess is the entire WSE3 has a unified power grid and there is no ability to voltage-tune their way out of parametric yield issues.
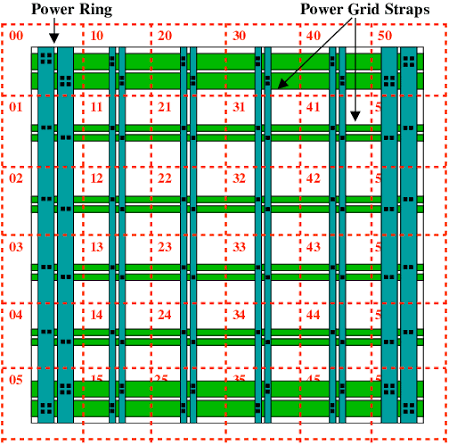
图 42|电源网格条带(Power Grid Straps)结构示意。
It is very suspicious that the CS-4 (with overclocked WSE3-turbo) doubled the clocks of everything. IO and core clock.
My conspiracy theory is they were operating at a hilariously low section of the volt/freq curve and managed to double because of improved cooling and reduced power supply ripple.
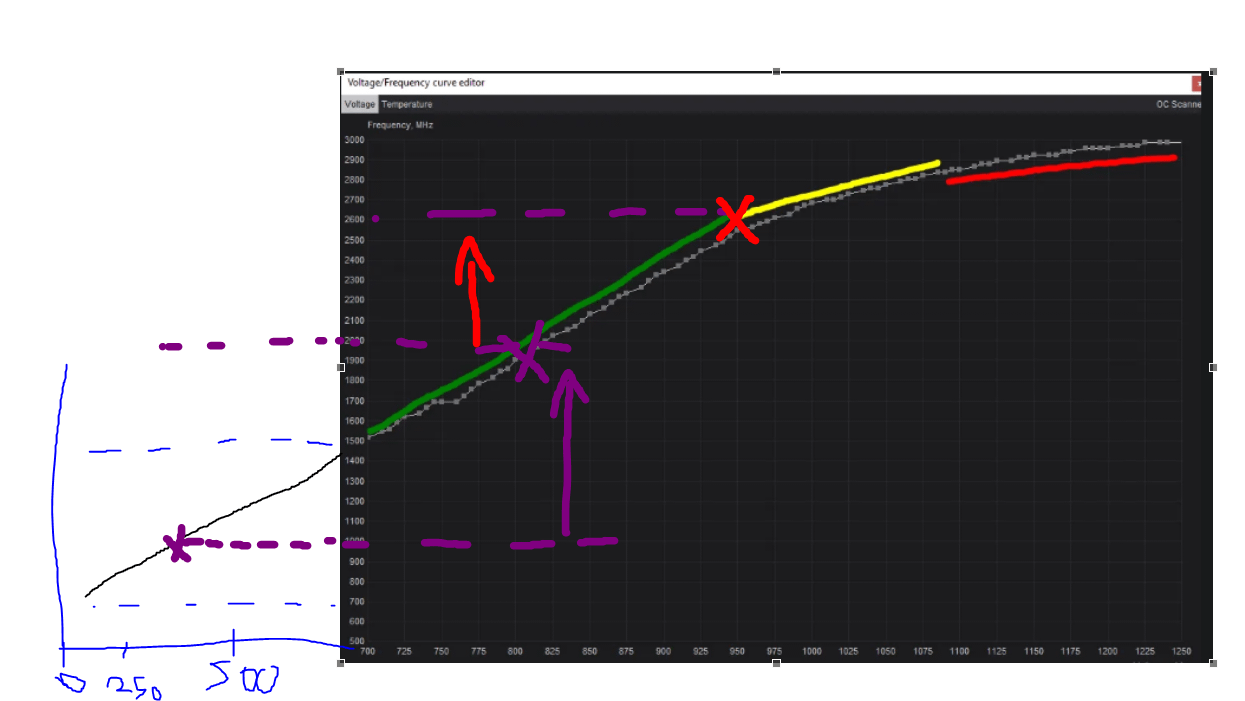
图 43|电压–频率曲线上的标注:Cerebras 当前所在位置与期望位置。
Ignore the absolute voltage and frequency numbers. I am using this chart because lazy.
Every chip has a volt/freq response that looks like this. Some threshold voltage to turn on at all, a linear region, a not so great region, then the asymptotic region where giving 20-25% more juice gives you 3-5% more speed.
I think Cerebras WSE3 and WSE3-turbo are at the purple Xs. The gain going from CS-3 to CS-4 is purple arrow. Red arrow and red X is where they would like to be but can’t for a variety of reasons where I can only speculate.
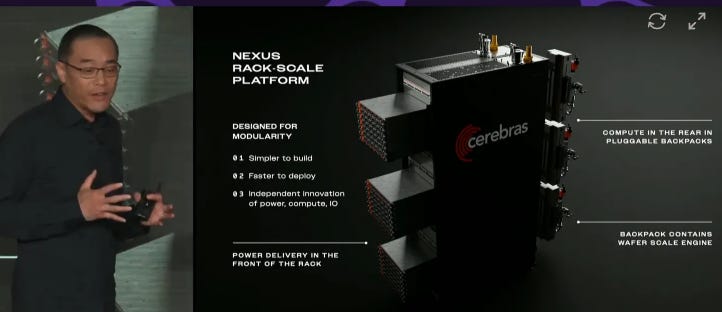
图 44|WSE-3 Turbo:在相同硅片上把主频提高 50%。
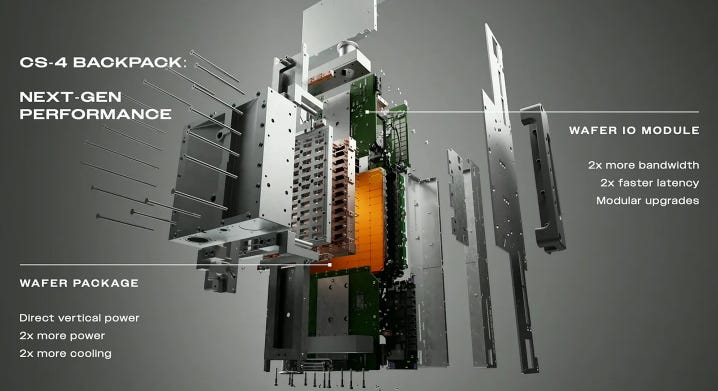
图 45|CS-4 机箱结构渲染图(Wafer Module / Sub-Node Box 与液冷分配)。
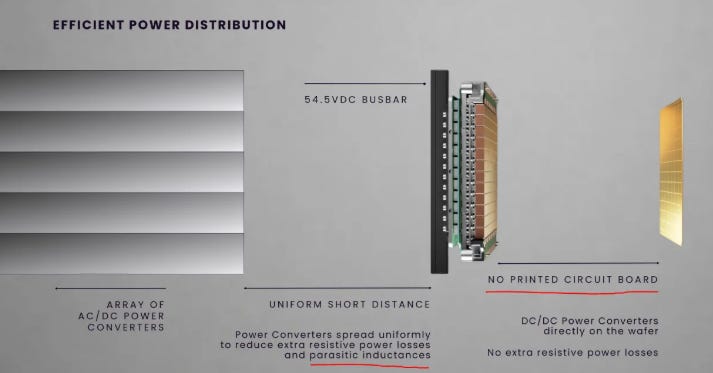
图 46|「Efficient Power Distribution」幻灯片:晶圆模块、子节点逻辑与电源板。
Note how JP called out resistive and inductive parasitics.
Parasitic resistance = power/efficiency loss
Parasitic inductance = power supply ripple = stability issues
Skewed corners (SF, FS) generally hate power supply ripple.
So on the enclosure, cooling, and power delivery fronts, Cerebras has made great progress.
I think the parametric (product-level) yield of this new system will be significantly better. They have supply issues now because this CS-4 product is only just starting to ramp. Probably have to wait until H1 2027 to see hardware revenue and gross margin inflection.
So the question is what can the next-gen WSE4 do to help with parametric yield?
Remember the WSE-3-turbo is the same silicon. Just doubled all clocks because of better thermal headroom and power supply stability.
Here is my list of ideas. All made up. I have no info just guesses based on experience.
Add granular voltage control by splitting up the power grids. The CS-4 renders look like the power delivery was modularized both for serviceability and for adjusting voltage of the WSE at a reticle or possibly more granular level.
Go a step further and add DVFS for the compute cores.
De-couple compute, SRAM, and NoC clocks.
New custom cells that are more tolerant to PVT. I suspect Cerebras used mostly standard PDK cells. Might be wrong on this.
As a summary // TLDR;
I believe Cerebras is getting killed by parametric yield issues which destroy hardware gross margins and severely limit supply.
Also believe CS-4 enclosure is great progress and should make their financials/numbers much better H1 2027.
There exist many possible vectors to drastically improve parametric yield further by making (admittedly significant) design changes in WSE4. Lot of potential here.
第二部分:中文结构化解读
零、速览
| 项目 | 内容 |
|---|---|
| 来源 | Irrational Analysis(Substack 半导体投资专栏) |
| 原文标题 | Practical Parametric Yield |
| 副标题 | (Featuring Cerebras) |
| 发布 | 2026 年 10 月 4 日(北京时间当日晚) |
| 篇幅 | 约 4,450 词,46 张配图 |
| 可见性 | 全文公开,未设付费墙 |
| 一句话主题 | 决定芯片「跑多快、耗多少电、卖多少钱」的不是设计,而是参数良率——而它本质上是商业选择 |
| 为什么此刻读 | Cerebras 的晶圆级路线把参数良率问题放大到了整个行业最极端的形态 |
原文语气强烈、多处使用粗口与情绪化措辞(例如称 2024 年那场发布会为 a fucking disaster),并包含若干指向具体公司与个人的归因。本站第一部分逐字保留原貌、未作删改;下面第二部分的判断语言已保持中性,并单独标注了哪些是作者的行业叙事、哪些是可独立验证的工程事实。
一、文章的骨架
原文是一条罕见的「自下而上」叙事:作者不是从投资逻辑出发,而是从自己做过的工作(后硅验证,post-silicon validation)出发,反过来推出对一家公司的判断。
- 良率有两种,混淆它们是行业里最常见的错误。 灾难性良率(缺陷、缺陷密度)决定「这颗芯片能不能用、有多少核是活的」;参数良率决定「活着的部分能跑多快、耗多少电」。前者是物理问题,后者是分配问题。
- 现实是高斯分布。 光刻、刻蚀、沉积的波动最终都变成器件参数的分布:阈值电压、漏电、上升时间、寄生电阻……设计按 ±2σ 留余量,工艺厂用「特征化批次」事先标注工艺角,后硅验证找出一套让所有角都通过的默认配置,然后才进入「工艺角事先未知」的量产。
- 参数良率是经济选择。 同一颗硅片可以做成四档频率/功耗的产品(AMD Turin 的四个 64 核 SKU 就是范例),这就是「良率收割」。时钟频率不是设计师追求的目标,而是产品管理在看完后硅验证数据之后做的商业决定。
- 偏离现实的幅度有量纲。 在 ±2σ / ±10% 的既定余量下,主频差 5–10% 是小失误,15% 是严重问题,25% 就是灾难。作者用这条标尺去读 SemiAnalysis 关于 OpenAI Jalapeño「B0 比 A0 主频高 25%」的说法,得出与原文相反的结论。
- 这行的三种活法:先做出来、做得更聪明,或者作弊。 作弊之所以可行,是因为半导体极度复杂、内部部门之间互相看不见。作者举了若干亲历或旁观的例子(演示条件不披露、被隐藏的调试寄存器、竞品把 −18% 欠压说成安全)。
- Cerebras 被这套机制以最狠的方式惩罚。 它必须在一片晶圆上让 84 个 reticle 同时达到可接受的参数良率;既不能丢弃慢的,也不能降级成低端 SKU;更致命的是它缺少经济可行的系统级测试台——必须先把昂贵的定制垂直供电与散热装好,才能知道这颗产品行不行。
二、核心机制拆解
| 主张 | 原文给出的证据 | 我的判断 |
|---|---|---|
| 参数良率与灾难性良率是两件事 | AMD Turin 四个 64 核 SKU 共用同一设计,功耗差 33%;NVIDIA 的 TI/Super 分档;GP104 一颗设计出两个产品 | 成立且可独立验证。这是全文最有价值的一条:只要去看各家的 SKU 表,就能看到参数良率在起作用。 |
| 参数良率约 95% | 作者的经验值(假设设计、工艺、验证三方都做对) | 数字可用,但口径需要限定:它指的是「已按 ±2σ 留余量并完成后硅调优之后的稳态」。把它当成行业平均值去对比 Cerebras,会高估差距的普遍性。 |
| 时钟频率是商业决定而非设计决定 | Schmoo 图;电压–频率的三区间(线性 / 收益递减 / 几乎无收益);AMD RX Vega 与 RTX 3000 被推到「黄区乃至红区」 | 成立。三区间模型在工程上很扎实,是理解「为什么同一颗芯片能出高端和低端两个 SKU」的关键。 |
| 偏离 25% 等于灾难 | 作者自设的量纲(5–10% / 15% / 25%);Jalapeño 的 N3P 节点背景 | 推论强度超过证据强度。25% 这个数来自对他人报道的转述,且口径未明(是最高频率差,还是同频 perf/W 差?);此外步进迭代常伴随物理实现与时序收敛目标的修改,其中一部分差异可能是有意为之。 |
| Cerebras 没有经济可行的系统级测试台 | 对比 Jalapeño 的插座式测试板(跳线、Samtec Bullseye、过建的供电、自动化热头);Cerebras 必须整机装配后才能测 | 方向成立,且可以量化得更狠:晶圆级方案把良率损失的粒度从「一颗 die + 若干 HBM」放大到「整片晶圆 + 定制供电 + 定制冷板 + 机箱」,而损失期望值随面积近似线性增长。这是 wafer-scale 最根本的经济学不对称,原文只说了「很贵」。 |
| 参数良率是 Cerebras 最被忽视的生存级问题 | 作者与 Sean、JP 的对话;Sean 在被问「每个 reticle 独立电压」时反复回避 | 属于作者的推断,没有可验证的硬证据。但推理链条自洽:若 WSE-3 是全晶圆统一电源网格,就无法用分区调压把慢的 reticle 拉回来。 |
| CS-4 把全部时钟翻倍,说明原来工作在电压–频率曲线的极低段 | WSE-3 Turbo 是同一颗硅,仅因散热与电源纹波改善就把时钟翻倍 | 有趣但不可验证。这个推论如果成立,含金量很高——它意味着 Cerebras 的性能天花板上限很大一部分被供电与热设计锁住了,而不是被硅本身。 |
| 拆电源网格、core DVFS、解耦 compute/SRAM/NoC 时钟、更抗 PVT 的定制单元是 WSE4 的方向 | 作者自称「全是猜的、没有任何内部信息」 | 工程上合理,但请注意这是外部推测清单,不是路线图。 |
三、关键数字清单
- 2σ:设计阶段模拟的工艺角范围。
- ±10% / ±5% / ±3%:电压的模拟范围 / 常规表征范围 / 更严的表征范围。
- −20 °C 与 +110 °C:标准温度角;−40 / +125 °C 为车规、工业、军工扩展角;0–70/90 °C 为常见的窄范围。
- ~95%:作者给出的稳态参数良率经验值。
- 33%:AMD Turin 家族中 9575F 相对 9535 的功耗差(同一设计)。
- 25%:SemiAnalysis 报道的 Jalapeño B0 相对 A0 的主频差——作者认为这是灾难级信号。
- 84:作者给出的单片晶圆上的 reticle 数量(Cerebras 需要在同一片晶圆上同时达标)。
- 30 °C:Lumentum 在 OFC 2026 的 UHP 演示结温;作者指出行业通常运行在 40 °C 及以上。
- −18% vs −12%~−14%:竞品对外宣称的安全欠压 vs 作者实测能安全承诺的欠压。
- 100 W / 10 个功能块 / 1000 个传感器:作者用来描述 DVFS 优化问题的示意规模。
- 2015 / 2019 / 2024 / 2026:Cerebras 成立、WSE-1、WSE-3、更新机箱的年份。
四、我的评述(原文没有的判断)
作者把参数良率当成一个标量,但它至少是三条独立的轴:最高频率(速度分档)、漏电与动态功耗(功耗分档)、以及同频下的能效点。绝大多数芯片公司三条轴都可用 SKU 与 DVFS 分别处理;Cerebras 的问题是三条轴同时被锁死——因为整片晶圆是一个产品,它不能分档。原文用「不能丢弃、不能降级」概括了这一点,但没有指出「三条轴同时失效」才是真正的死结。
「25% 就是灾难」这条标尺的方向是对的,但需要补一个前提:只有在 A0 与 B0 之间除了「修 bug」之外什么都没改时,25% 才能被完整归因于失败。步进迭代通常会同时修改物理实现、改变时序收敛目标,甚至替换单元库。因此更稳妥的表述是「25% 说明 A0 阶段的某种假设严重不成立」,而不是「某人搞砸了」。
作者对「作弊」的界定有可操作性不足的问题。 Lumentum 的 30 °C、Marvell 的激进冷却,严格说属于披露不完整,而不是数据造假。要让这条批判真正可用,应该给出三项披露清单:结温、通道损耗、器件是否经过精选(cherry-pick)。三项齐备即为合规营销,缺一项才进入灰色地带,主动伪造才是欺诈。原文把这三种情况混在同一段落里,削弱了说服力。
「没有经济可行的测试台」这一条,可以进一步推出一个对投资更有用的结论:晶圆级方案的良率损失不可分散。常规芯片可以把「封装后测试失败」的损失限制在一颗 die 加几颗 HBM 的范围内;晶圆级方案一旦失败,损失的是整片晶圆以及与之绑定的定制供电与冷却组件。这意味着 Cerebras 的毛利率对参数良率的弹性,远高于同尺寸的传统方案——换句话说,CS-4 机箱带来的散热与电源改善,可能比任何架构改动都更能改善它的财务数字。作者提出了这个方向,但没把「为什么这对毛利率的影响是指数级而非线性」讲透。
原文最有传播力、也最容易被误读的一句是「参数良率是商业选择」。 正确的读法是:参数良率在既定硅片条件下由商业选择决定(要不要为高端 SKU 攒货、要不要把慢的清仓)。但分布的宽度本身是设计与工艺决定的技术结果。作者的表述容易被读成「良率是主观的、可以随便选」,这与他的本意相反。
关于 Jalapeño 的责任归属:作者把候选范围收窄到 Broadcom 或 OpenAI(及其 AI agent 写的 RTL),并明确说「你自己下结论」。我认为更有信息量的问题是A0 是否已经对外出货、客户是否受影响——原文没有回答,而这才是判断这件事严重程度的分水岭。
五、可采信度分层
- 高(可由公开资料独立验证):良率的两分法;yield harvesting 的机制(AMD / NVIDIA 的 SKU 表即可印证);工艺角与 ±2σ / ±10% / ±5% 的工程约定;温度角的分级;TDP 是「可持续」功耗而峰值可以远高;电压–频率曲线的三区间形态;Schmoo 图的形式。
- 中(推理合理但无量化):Cerebras 缺少经济可行的系统级测试台;参数良率的稳态水平约 95%;CS-4 时钟翻倍归因于散热与电源纹波改善;晶圆级良率损失不可分散。
- 低(不可独立验证):关于前雇主的调试寄存器事件;竞品 −18% 欠压的具体数字;WSE-3 使用统一电源网格的猜测;对 RX Vega 与 RTX 3000 的责任归因;对 Jalapeño 25% 差值的解读。
六、原文没有回答的问题
- Cerebras 的参数良率究竟是多少?有没有内部的降级/分档产品在卖?
- 「84 个 reticle 要在同一片晶圆上达标」的判据是什么——按最慢的 reticle 定频,还是按某种统计准则确定整片的工作点?这直接决定良率与性能的取舍曲线。
- 25% 这个数字的口径:最高频率、还是同频下的 perf/W、还是最优工作点?
- A0 是否已经出货?客户是否已经拿到、是否受影响?
- 若 WSE-3 确为统一电源网格,改成按 reticle 分区供电需要几层金属重做、几次流片?
- 作者提出「更抗 PVT 的定制单元」——Cerebras 是否真的主要使用标准 PDK 单元?这决定了这条建议的可行性。
七、原文内部值得注意的几处
- 「我不批评 Cerebras」与全文判断的落差。 作者反复声明不是在批评,但「参数良率是他们最不重视的生存级问题」在实质上就是对工程优先级的批评。这是措辞与内容之间的不一致。
- 「参数良率约 95%」的两种用法。 前文把它当作「所有人都做对之后」的工程常态,后文又用「偏离这个水平说明有人搞砸了」来推断事故——两处其实需要一个共同的误差预算定义,原文没有给。
- 情绪化措辞与信息密度的反差。 文章标题是 Practical,但大量篇幅是梗图、个人经历与行业八卦。这不构成错误,但读者需要自行区分「可迁移的工程知识」与「不可验证的个人叙事」。
- 对具体个人的归因。 文中对某位前高管的评价、以及对两家晶圆厂工艺质量的排序,属于行业内流传的解释,缺少可公开引用的证据。
八、与本站其他文章的连接
- Cerebras 与超低延迟推理:https://marvinlee.cn/posts/amd-cerebras-ultra-low-latency-ai-inference/ —— 理解 Cerebras 在推理场景里的定位,与本文的「供给受限」判断互为补充。
- 供电与电源完整性:https://marvinlee.cn/posts/mlcc-silicon-capacitor-power-integrity/ —— 原文把电源纹波与寄生电感视为 CS-4 提速的关键,这一篇讲的是同一件事在板级的物理基础。
- 测试为何是投资标的:https://marvinlee.cn/posts/semiconductor-test-a-compelling-investment/ —— 与本文「Cerebras 缺少经济可行的测试台」形成对照。
- 先进封装:https://marvinlee.cn/posts/a-masterclass-on-advanced-packaging/ —— Wafer-scale 的封装与散热是这篇的极端案例。
- 晶体管缩放与工艺变异的物理来源:https://marvinlee.cn/posts/gate-all-around-complementary-fets-whats-next-transistor-scaling/ —— 工艺角分布的上游成因。
- AI 芯片设计的经济学:https://marvinlee.cn/posts/redwood-ai-designed-ai-chip/ —— 另一条「用设计换供给」的路径。
九、一句话结论
这篇文章的真正价值不在于它对 Cerebras 的看多看空,而在于它给出了一把量尺:参数良率决定同一颗硅片能卖几个价钱、能跑多快,而 wafer-scale 的代价是——这把尺子上的每一档,Cerebras 都不能选。